
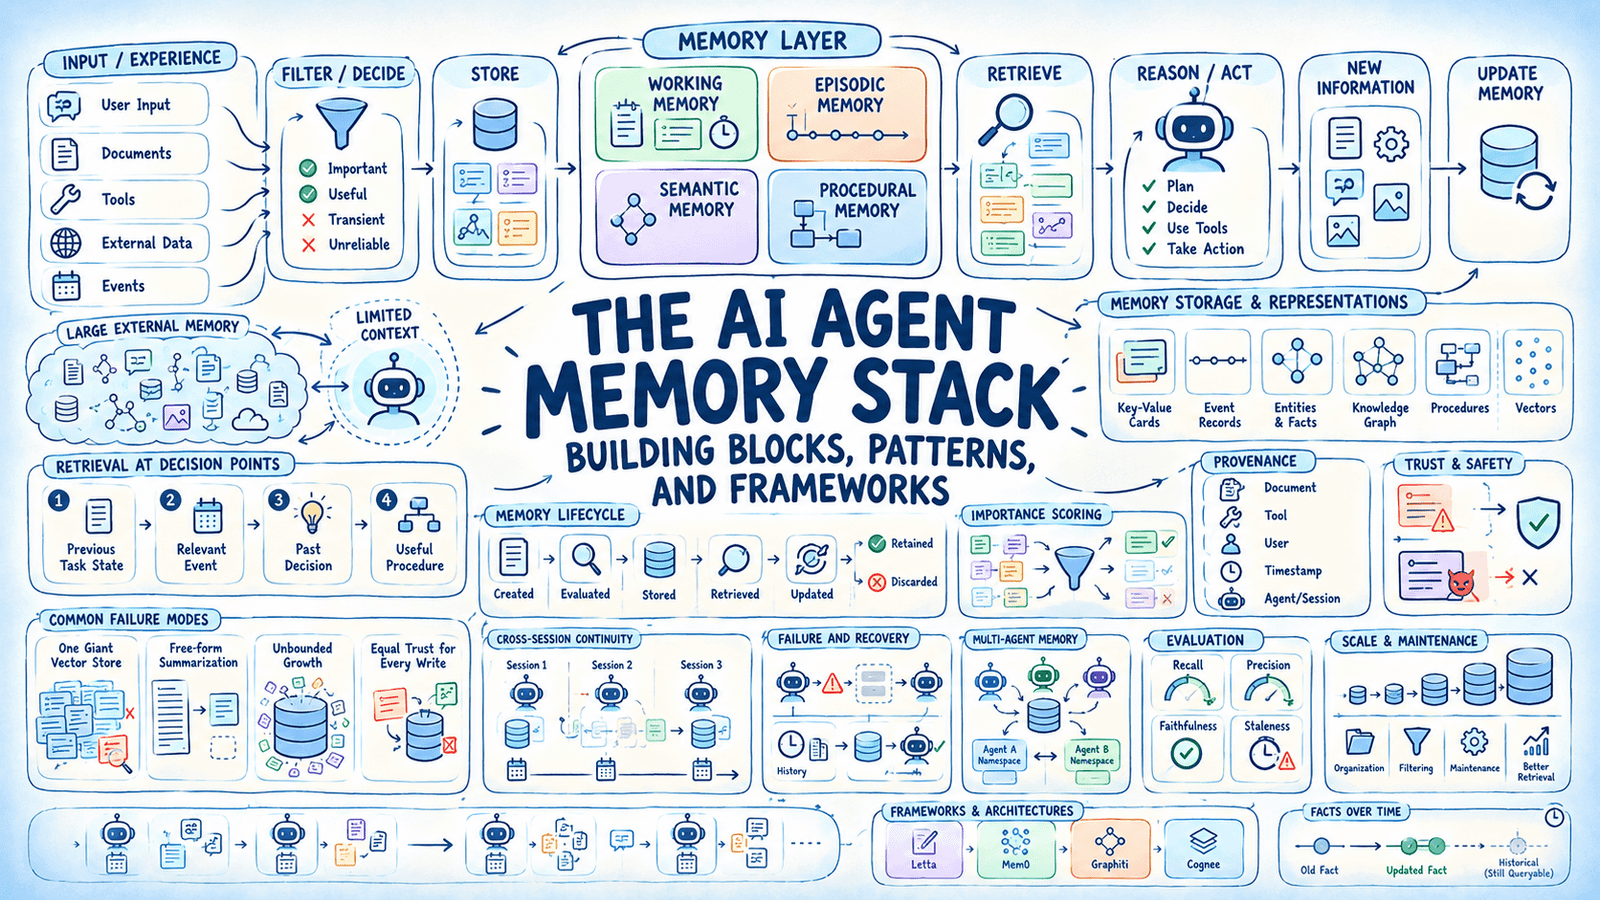
In this article, you will learn how agent memory works, what types of memory exist, and how different frameworks approach storage, retrieval, and memory management at scale. Topics we will cover include: The core memory types used in AI agents and what each one is designed to store. Practical design strategies for writing, retrieving, and maintaining agent memory reliably. How leading memory frameworks differ in their storage models, retrieval approaches, and handling of fact changes over time. Introduction A language model does not retain information between calls. Each time it runs, it works with the text provided in that request and does not automatically remember what happened before. This works well for simple, one-off questions, but AI agents need more when they have to track previous actions, remember user preferences, or continue a task across multiple steps. Memory solves this by storing information outside the model’s context window and making it available when needed. But agent memory is not a single mechanism. Different types of memory serve different purposes, while different storage and retrieval patterns affect how reliably that information can be used. This article covers: The building blocks: what memory types exist and what each one is for How agents store, retrieve, and update information reliably How different frameworks handle memory storage, retrieval, and organization We start with the building blocks. The Building Blocks of Agent Memory Before looking at memory frameworks and implementation patterns, it helps to define what agent memory needs to store. Different tasks require different kinds of information, and each type of memory has its own role, storage model, and retrieval strategy. Why Agents Need Memory at All Agents often need to carry information across calls and tasks. They may need to remember what has already been scheduled to avoid duplicate actions, retain a user’s preferences across sessions, or carry forward information discovered during a multi-step task. They may also need to remember failed approaches so they do not repeat the same work. Without memory, each call starts with only the information in its current context. The agent has no reliable way to know what happened before or what it has already learned. Agent Memory Types Agent memory falls into the following types, each suited to a different kind of information and retrieval pattern. The table below shows what each memory type holds, where it is typically stored, and how it is retrieved: Memory Type What It Holds Storage Layer Retrieval Method Working Active task state: intermediate results, scratchpad values In-memory or short-lived key-value store Direct lookup by key Episodic What happened: past interactions, task runs, decisions made Time-ordered log or vector store Semantic similarity search Semantic What is true: facts and preferences that get updated rather than appended Key-value or entity store Exact lookup by attribute, sometimes combined with semantic search Procedural How to do things: successful action patterns, known failure modes Prompt templates or fine-tuning Pattern match or direct injection Working memory is the information currently available in the context window. The other memory types determine what information should be brought into that context. Episodic memory captures past events, while semantic memory stores facts about entities, users, or the environment. Keeping these distinctions clear makes memory easier to store, retrieve, and maintain. Agent Memory Design Strategies Knowing the different memory types is only the starting point. The more substantial part is deciding what should be stored, when it should be written, how long it should remain, and when it should be retrieved. These decisions determine whether memory stays useful as an agent runs longer tasks and accumulates more information. A Worked Example: A Multi-Step Research Agent Consider a research agent working on a task over several days: gathering sources, extracting claims, drafting sections, and repeating the process. After each step, the agent writes the result to working memory with a short expiry. Each entry is tagged with basic metadata, such as the tool that produced it and the session it belongs to. When a result proves useful, it can be promoted to episodic memory with an importance score. A temporary observation may be discarded, while a decision that affects later steps can be retained. Before each tool call, the agent checks working memory for relevant state and then searches episodic memory when additional context is needed. Retrieval happens at each decision point rather than only once at the beginning, because the information that matters can change as the task progresses. If the task fails halfway through, the agent can discard the temporary working state while retaining the episodic record of completed work. When the task resumes, it can use that history instead of starting from scratch. Memory Design Strategies That Work A few practices consistently make memory systems more reliable as they grow: Score memory importance before writing: Filter out transient observations and low-value tool outputs so the store stays focused on information that is likely to matter later. Scope memory by agent role: In multi-agent systems, keep each agent’s memory focused on its responsibilities to reduce irrelevant or conflicting information. Retrieve at decision points: Refresh context throughout a workflow instead of retrieving memory only when the task starts. Track provenance: Record where each memory came from, such as the agent, tool, user input, or timestamp. This makes memory easier to debug and audit. Together, these practices help keep memory relevant as tasks become longer and the amount of stored information increases. Memory Design Strategies That Don’t Always Work Some approaches are simple to implement but become unreliable as the memory store grows. The table below covers common approaches and the problems they introduce: Approach Why It Fails Embedding everything into one vector store Retrieves information that is semantically similar but not necessarily relevant to the task, while making relationships between facts difficult to represent. Free-form summarization as memory compression Can remove specific details, constraints, or numbers that become important later, and may preserve an incorrect statement as if it were verified. Unbounded memory growth with no maintenance Causes irrelevant entries to
7 Ways Your AI Agent Is Wasting Tokens (And What to Do Instead)
In this article, you will learn seven common token-waste patterns in production AI agent systems, and the architectural fixes that address each one. Topics we will cover include: How treating the context window as a system of record inflates costs and latency, and how to fix it with sliding windows and semantic summarization. How uncompressed tool results, static schema bloat, and naive retrieval patterns silently drain your token budget. How to use circuit breakers, prompt prefixing, cascaded routing, and constrained output formats to build cost-stable agent architectures. Introduction Prototyping an agent over a weekend is one problem. Keeping its API bill from spiraling by month three is another. The naive approach to agent architecture — appending every user message, observation, and internal response to an endlessly growing array — quadratically increases inference latency and linearly inflates token costs on every call. The root of this failure is treating the context window as a system of record. There’s a distinction many engineers miss early on: Context is the ephemeral token payload sent over the wire per request. State is the durable, serialized representation of the agent’s progress. Conflate the two and you’re paying for your database reads on every single inference call. This tutorial covers seven of the most common and costly token-waste patterns in production agent systems, along with the architectural fixes that address each one. 1. Context Window Accumulation (The Append-Only Trap) The most widespread mistake in agent design is treating the prompt array as a database. Every turn gets appended — user messages, tool observations, intermediate reasoning, assistant responses. By turn 20, the agent is re-reading its entire operational history on every request, paying quadratically increasing attention costs to do so. The fix: Implement a sliding context window with semantic rolling summarization. Pass only the last N turns verbatim. Compress older conversational turns into a dense background summary, and offload structural agent state to a deterministic store like SQLite or Redis rather than injecting those values back into the prompt. The catch: Summarization is inherently lossy. If an agent needs exact UUIDs, cryptographic hashes, or code snippets from early in a session, semantic compression will hallucinate them. Pair this pattern with a strict key-value lookup tool that retrieves exact strings when precision matters. When to use it: This should be the default architecture for any long-lived conversational agent or iterative reasoning loop expected to exceed five to ten turns. 2. Uncompressed Tool Result Ingestion When an agent calls a third-party API, it often receives a deeply nested JSON payload designed for machines, not language models. Dumping that raw response into the observation context is one of the most avoidable sources of token waste. A single Stripe webhook payload or verbose AWS API response can consume thousands of tokens, most of which contain nothing the agent will ever reason about. The fix: Inject a middleware transformation layer between tool execution and context injection. This layer strips null values, filters non-essential keys, and reformats deep JSON into dense YAML or structured Markdown. For logs, a deterministic pre-processing pass can strip timestamps, thread IDs, and boilerplate before the model sees the data. The catch: Aggressive filtering sometimes removes necessary metadata, like pagination cursors. If the agent needs to paginate through a list of results, stripping the next_token field to save a handful of tokens will silently break the entire retrieval loop. When to use it: Whenever integrating third-party APIs — Stripe, Jira, AWS — that return verbose payloads optimized for machine consumption rather than language model reasoning. 3. Retrieval Thrash and “Grep-and-Dump” In coding agents and RAG-heavy systems, a common pattern is using naive text matching to find relevant content, then dumping entire files into the context window. The agent needs a single function, so the orchestrator retrieves the entire 4,000-line file it lives in. It’s the retrieval equivalent of reading an entire encyclopedia to answer one question. The fix: Shift to chunked, AST-aware (Abstract Syntax Tree) retrieval. During indexing, parse code into a live call graph. When the agent searches for a function, the orchestrator queries the index and returns only the exact function signature, its docstring, and immediate structural dependencies. That’s 300 tokens instead of an entire file. Libraries like Tree-sitter make it straightforward to build language-aware parsers that extract these structural units accurately. The catch: Graph-aware retrieval requires continuous, asynchronous indexing pipelines. If the vector index lags behind the repository’s main branch, the agent will reason confidently about stale state, attempt to call functions that no longer exist, and burn output tokens working through the resulting errors. When to use it: Building coding agents, RAG-heavy support bots, or any system interacting with rapidly mutating, highly structured codebases. 4. Static Tool Schema Bloat Most agent frameworks define tool schemas once and inject all of them on every LLM call. For a small tool registry this is harmless. For an agent with 30 or 50 tools, the model is reading thousands of tokens of schema definitions on every request — including schemas for tools that are completely irrelevant to the current task phase. The fix: Implement context-aware tool pruning governed by a finite state machine. The agent’s current operational state dictates which tools are injected. An agent in a “discovery” state receives only search and read tools. Once it transitions to “execution,” it receives only mutation and write tools. The irrelevant schemas never consume tokens. The catch: Dynamic tool schemas interfere with prompt caching. Every time the tool subset array changes, the LLM provider must recompute the KV cache for the affected prompt prefix, resulting in higher latency and missed cache-hit discounts. This creates a direct tension with the advice in section six. When to use it: Multi-agent architectures or solo agents with large tool registries where schema definitions alone exceed roughly 1,500 tokens of the context budget. 5. Unbounded Chain-of-Thought Loops Autonomous agents can get stuck. A tool call fails, the agent retries, the retry fails for the same underlying reason, and the agent keeps generating reasoning and
Speculative Decoding Explained: How to Get 3× Faster Inference from Any LLM
In this article, you will learn how speculative decoding works, why it produces real speed gains at the hardware level, and what modern implementations look…
Fine-Tuning vs. Frozen Embeddings: When to Adapt the LLM vs. the Sklearn Head
In this article, you will learn how to compare two strategies for adapting a large language model to a specific domain: fine-tuning with LoRA versus training a scikit-learn classifier on frozen embeddings. Topics we will cover include: How frozen embeddings work as a lightweight alternative to full model fine-tuning, and when this approach is appropriate. How to implement QLoRA fine-tuning using the PEFT library with a Hugging Face model and a classification head. How the two strategies compare in terms of training time and classification accuracy on a real dataset. Introduction When adapting an LLM (a large language model) to a specific domain, the classical approach picked by the machine learning community boils down to fine-tuning the model on a domain-specific dataset. But a question arises: is this always necessary? Or could alternative strategies like using frozen embeddings combined with lightweight downstream classifiers on top of the model be a wiser approach to adopt, especially when building cost-friendly, compute-constrained applications? This article presents a practical comparison of fine-tuning a local LLM with LoRA (Low-Rank Adaptation, an algorithm for efficient weight updating) against training only a downstream scikit-learn classifier on frozen embeddings. We cover, analyze, and discuss when each strategy is preferred based on cost and performance. To make the most of the practical example below, we recommend a basic level of familiarity with LLMs, key processes like model fine-tuning, and associated libraries like Hugging Face’s transformers. Initial Setup If you are running this practical comparison on Google Colab, first and foremost, make sure you set the running environment to GPU (T4), as the code and methods used in it are optimized for GPU use. You will only need to install the following libraries: !pip install -q -U bitsandbytes peft accelerate evaluate !pip install –q –U bitsandbytes peft accelerate evaluate Otherwise, if you are in a different Python environment, make sure to have scikit-learn, transformers, and datasets also installed before proceeding. We start by making some of the imports needed and loading a canonical dataset from the Hugging Face repository: ag_news, containing categorized news articles. import torch import numpy as np import time from datasets import load_dataset from transformers import AutoTokenizer, AutoModelForSequenceClassification, BitsAndBytesConfig # To use Llama-3 instead, change this to “meta-llama/Meta-Llama-3-8B” MODEL_ID = “Qwen/Qwen2.5-1.5B” print(“1. Loading dataset…”) dataset = load_dataset(“fancyzhx/ag_news”) # A tiny subset is used so that the comparison can be run in minutes, not hours, on GPU train_subset = dataset[“train”].shuffle(seed=42).select(range(800)) test_subset = dataset[“test”].shuffle(seed=42).select(range(200)) import torch import numpy as np import time from datasets import load_dataset from transformers import AutoTokenizer, AutoModelForSequenceClassification, BitsAndBytesConfig # To use Llama-3 instead, change this to “meta-llama/Meta-Llama-3-8B” MODEL_ID = “Qwen/Qwen2.5-1.5B” print(“1. Loading dataset…”) dataset = load_dataset(“fancyzhx/ag_news”) # A tiny subset is used so that the comparison can be run in minutes, not hours, on GPU train_subset = dataset[“train”].shuffle(seed=42).select(range(800)) test_subset = dataset[“test”].shuffle(seed=42).select(range(200)) Next, we load the model instance and its associated tokenizer, ensuring it is configured with a classification head compatible with the specific problem (dataset) at hand, in which news articles are classified into four possible classes: print(“2. Configuring Tokenizer…”) tokenizer = AutoTokenizer.from_pretrained(MODEL_ID) tokenizer.pad_token = tokenizer.eos_token # Necessary for decoder-only models print(“3. Loading Base Model in 4-bit…”) bnb_config = BitsAndBytesConfig( load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16, bnb_4bit_quant_type=”nf4″ ) # Loading the model with a classification head model = AutoModelForSequenceClassification.from_pretrained( MODEL_ID, num_labels=4, quantization_config=bnb_config, device_map=”auto” ) model.config.pad_token_id = tokenizer.pad_token_id 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 print(“2. Configuring Tokenizer…”) tokenizer = AutoTokenizer.from_pretrained(MODEL_ID) tokenizer.pad_token = tokenizer.eos_token # Necessary for decoder-only models print(“3. Loading Base Model in 4-bit…”) bnb_config = BitsAndBytesConfig( load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16, bnb_4bit_quant_type=“nf4” ) # Loading the model with a classification head model = AutoModelForSequenceClassification.from_pretrained( MODEL_ID, num_labels=4, quantization_config=bnb_config, device_map=“auto” ) model.config.pad_token_id = tokenizer.pad_token_id Strategy A: Frozen Embeddings & Scikit-learn We start by trying out the alternative to fine-tuning our model. It works as follows: instead of retraining the LLM, we make it act strictly as a feature extractor. We pass the text through this “frozen model” (one in which weights cannot change) and extract the last hidden state (the embedding vector) for the final token. These high-dimensional embeddings are then fed to an auxiliary model — in other words, they are used to train a traditional lightweight classifier on top of the frozen LLM. The first step is defining a function with the internal logic to obtain the frozen embeddings from input texts: from sklearn.ensemble import RandomForestClassifier from sklearn.metrics import accuracy_score def extract_embeddings(texts, batch_size=8): model.eval() embeddings = [] for i in range(0, len(texts), batch_size): batch = texts[i:i+batch_size] inputs = tokenizer(batch, return_tensors=”pt”, padding=True, truncation=True, max_length=128).to(model.device) with torch.no_grad(): # output_hidden_states=True forces the model to return the raw vectors outputs = model(**inputs, output_hidden_states=True) last_hidden_state = outputs.hidden_states[-1] # Mean pooling: averaging the vectors across the sequence length, ignoring padding tokens mask = inputs[“attention_mask”].unsqueeze(-1).float() sum_embeds = torch.sum(last_hidden_state * mask, dim=1) mean_pooled = sum_embeds / torch.clamp(mask.sum(dim=1), min=1e-9) embeddings.append(mean_pooled.cpu().numpy().astype(np.float32)) return np.concatenate(embeddings, axis=0) 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 from sklearn.ensemble import RandomForestClassifier from sklearn.metrics import accuracy_score def extract_embeddings(texts, batch_size=8): model.eval() embeddings = [] for i in range(0, len(texts), batch_size): batch = texts[i:i+batch_size] inputs = tokenizer(batch, return_tensors=“pt”, padding=True, truncation=True, max_length=128).to(model.device) with torch.no_grad(): # output_hidden_states=True forces the model to return the raw vectors outputs = model(**inputs, output_hidden_states=True) last_hidden_state = outputs.hidden_states[–1] # Mean pooling: averaging the vectors across the sequence length, ignoring padding tokens mask = inputs[“attention_mask”].unsqueeze(–1).float() sum_embeds = torch.sum(last_hidden_state * mask, dim=1) mean_pooled = sum_embeds / torch.clamp(mask.sum(dim=1), min=1e–9) embeddings.append(mean_pooled.cpu().numpy().astype(np.float32)) return np.concatenate(embeddings, axis=0) Next, we call the function passing our dataset sample — already split into training and test subsets — and obtain the frozen embeddings that will be used to train and test a random forest classifier: print(“Extracting embeddings…”) start_time = time.time() X_train = extract_embeddings(train_subset[“text”]) X_test = extract_embeddings(test_subset[“text”]) y_train = train_subset[“label”] y_test = test_subset[“label”] embed_time = time.time() – start_time print(“Training Scikit-Learn Random Forest…”) clf = RandomForestClassifier(n_estimators=100, random_state=42)
Robust Serialization with JSON and Custom Types
In this article, you will learn how to build a robust JSON serialization pipeline in Python that handles custom data types, graceful error recovery, and…
Context Managers Beyond Opening Files in Python
In this article, you will learn how Python context managers work beneath the surface, and how to apply them to real cleanup problems well beyond file handling. Topics we will cover include: How the with statement’s protocol works, including what __enter__() and __exit__() actually do and why the return value of __exit__() matters. How to build custom context managers using a class, the @contextmanager decorator, and standard library tools like TemporaryDirectory and patch.dict(). How to manage a runtime-variable number of resources safely using ExitStack, and when to wrap it in a class of its own. The evaluation script does a fair amount of housekeeping before it evaluates anything. There is a scratch directory for the extracted test set, an environment variable that points the model cache at a faster disk, a library logger turned down to WARNING because it otherwise floods the console, and a stopwatch. The bottom of the file undoes all of it in the right order: the directory is deleted, the variable restored, the logger reset, the elapsed time printed. The cleanup at the bottom runs every time the script succeeds. The day a malformed record makes evaluate() raise halfway through, none of it runs. Whoever uses the machine next gets a stale cache path, a logger that has gone quiet for no reason they can see, and 3 GB of extracted files nobody remembers creating. scratch = Path(“scratch”); scratch.mkdir(exist_ok=True) os.environ[“MODEL_CACHE”] = “/fast/cache” logging.getLogger(“transformers”).setLevel(logging.WARNING) start = time.perf_counter() scores = evaluate(model, extract(archive, scratch)) # raises on a bad record print(f”took {time.perf_counter() – start:.1f}s”) # none of this runs shutil.rmtree(scratch) del os.environ[“MODEL_CACHE”] logging.getLogger(“transformers”).setLevel(logging.INFO) scratch = Path(“scratch”); scratch.mkdir(exist_ok=True) os.environ[“MODEL_CACHE”] = “/fast/cache” logging.getLogger(“transformers”).setLevel(logging.WARNING) start = time.perf_counter() scores = evaluate(model, extract(archive, scratch)) # raises on a bad record print(f“took {time.perf_counter() – start:.1f}s”) # none of this runs shutil.rmtree(scratch) del os.environ[“MODEL_CACHE”] logging.getLogger(“transformers”).setLevel(logging.INFO) Most Python developers meet context managers through with open(path) as f, learn that the file gets closed, and stop there. Files are the least interesting thing a context manager can manage. What the with statement really provides is a block with a guaranteed exit. Setup happens at the top, cleanup at the bottom, and the cleanup runs whether the middle succeeded or threw. If cleanup has to happen even when the block fails, why leave it outside the block? Each of the four things the evaluation script sets up is a temporary contract. Each can be a context manager: a timer that cannot forget to stop, a directory that removes itself, a state change that reverses itself, and a stack of resources that unwinds in the right order. That is the progression here, from the protocol underneath with through the standard library’s shortcuts to a rule for choosing between them. The With Statement Is a Boundary, Not a File Trick The language reference describes the with statement as a sequence, and the sequence is worth holding in your head. Every pattern below is a variation on it. Python evaluates the expression after with to get a context manager and calls its __enter__(). Whatever __enter__() returned is bound to the name after as, the block runs, and then __exit__() is called. The last step is the whole point. It happens on a normal exit, on a return from inside the block, and on an exception, so no path through the block can skip the cleanup written in __exit__(). Two details trip people up, and both concern return values. First, as name receives whatever __enter__() returns, which is often the manager itself but doesn’t have to be. open() returns the file, and TemporaryDirectory() returns a path string. Second, __exit__() receives three arguments describing the exception, or three None values on a clean exit, and its own return value decides what happens next. The data model is precise about this. Return a true value and the exception is suppressed. Return False, or fall off the end and return None, and the exception propagates after cleanup. class Announce: def __enter__(self): print(“enter”) return “the value bound after as” def __exit__(self, exc_type, exc_value, traceback): print(“exit”, exc_type) # None on a clean exit return False # let any exception propagate with Announce() as x: print(x) class Announce: def __enter__(self): print(“enter”) return “the value bound after as” def __exit__(self, exc_type, exc_value, traceback): print(“exit”, exc_type) # None on a clean exit return False # let any exception propagate with Announce() as x: print(x) The suppression rule is the one to get right first. Getting it wrong is silent. A __exit__() that ends with return True turns every exception inside the block into nothing, and so does one that returns the result of a cleanup call which happens to be truthy. The script keeps running, the scores are missing, and the traceback that would have explained why was eaten at the block boundary. The custom managers below never return anything truthy from __exit__(). Whatever went wrong inside the block stays the caller’s problem, which is where it belongs. The guarantee in one picture: both routes out of the block go through __exit__(), and on the exception route its return value is the only thing standing between the error and the caller. Credit: original diagram based on the Python language reference for the with statement and the data model. Build a Timer That Cannot Forget to Stop The stopwatch in the opening script is the smallest case of the pattern. Two calls to time.perf_counter() bracket the work, and the second call is exactly the kind of line an exception skips. A class with __enter__() and __exit__() moves that second call somewhere it cannot be skipped. import time class Timer: def __init__(self, label): self.label = label self.elapsed = None def __enter__(self): self._start = time.perf_counter() return self def __exit__(self, exc_type, exc_value, traceback): self.elapsed = time.perf_counter() – self._start status = “failed” if exc_type else “ok” print(f”{self.label}: {self.elapsed:.3f}s ({status})”) return False # never swallow the block’s exception with Timer(“feature extraction”) as t: features = extract(batch) print(t.elapsed) # still readable after the
How (and Why) to Build an AI Agent from Scratch in Python
In this article, you will learn what an AI agent is and how to build one from scratch in plain Python using the Anthropic API, without relying on any orchestration framework. Topics we will cover include: Why tool calling is necessary and how to define a tool the model can use. How to implement the request-execute-respond loop that drives an agent’s behavior. How to add persistent memory so the agent maintains context across multiple turns. Introduction A simple call to a large language model is enough when the answer can be produced from what the model already knows: explaining a policy, drafting a reply, summarizing text. It is not enough once the answer depends on data outside that training set, such as a live order status or a row in your database; this gap is what an agent is built to close. An AI agent is what results once the model can call out to something else — a function, a database query, an API — and use the result before it answers. Reaching for an agent orchestration framework to get this working is a reasonable move, eventually. Writing one from scratch in plain Python, using a raw API call, makes the underlying architecture clear. At its core, there is simply a model, a loop that manages the interaction, and a small set of well-defined functions that give the model the capabilities it needs. Stripping away the frameworks and abstractions makes it easier to see how these pieces fit together and what is actually happening under the hood. This article covers: Why tool calling is necessary and what you need installed to try it How to describe a tool so the model knows when and how to call it What the request-execute-respond loop looks like in code How to add memory so the agent keeps context across turns You can find the companion code for this article in this GitHub repository. Prerequisites You need Python 3.10 or later, an Anthropic API key, and the Anthropic Python SDK: Set your key as an environment variable so the client picks it up without hardcoding it anywhere: export ANTHROPIC_API_KEY=”your-key-here” export ANTHROPIC_API_KEY=“your-key-here” This is all you need to get started. You can find all the code in the agent.py script. ⚠️ A note to readers: Anthropic will officially retire Claude Sonnet 4.5 on November 30, 2026. If you are following this tutorial after that date, the specific model code used in these examples will no longer work. To ensure your project runs smoothly, replace the model string in the API calls with a newer version or the latest available model. Setting Up the Model Call A minimal wrapper around the API is a function that sends a prompt and returns text: import anthropic client = anthropic.Anthropic() def ask(prompt): response = client.messages.create( model=”claude-sonnet-4-5″, max_tokens=512, system=”You are a helpful support assistant. Be direct and factual.”, messages=[{“role”: “user”, “content”: prompt}], ) return response.content[0].text import anthropic client = anthropic.Anthropic() def ask(prompt): response = client.messages.create( model=“claude-sonnet-4-5”, max_tokens=512, system=“You are a helpful support assistant. Be direct and factual.”, messages=[{“role”: “user”, “content”: prompt}], ) return response.content[0].text This handles a large share of questions well — explaining a policy, drafting a reply, summarizing a paragraph. It fails the moment the answer depends on data the model was never shown. Ask ask(“What is the status of order #4471?”) and the model has no mechanism to check: that information lives in your database, not in its training data. It either states that it does not know, or produces a plausible answer anyway, and no amount of prompting changes that, since no prompt grants the model access to data it was never given. Tool calling gives the model a defined way to request that data instead of inferring it. Read The Roadmap to Mastering Tool Calling in AI Agents to learn more. Defining a Tool the Model Can Ask For Giving the model access to a function means writing the function, and writing a description of it that the model can read. The description matters because it tells the model what the function does and when to reach for it. orders_db = { “4471”: {“status”: “shipped”, “carrier”: “UPS”, “eta”: “2 days”}, “4472”: {“status”: “processing”, “carrier”: None, “eta”: None}, } def get_order_status(order_id): return orders_db.get(order_id, {“error”: “No order found with that ID”}) get_order_status_schema = { “name”: “get_order_status”, “description”: ( “Looks up the current status of a customer order by its ID. “ “Use this any time a question depends on current order data “ “rather than general policy information.” ), “input_schema”: { “type”: “object”, “properties”: { “order_id”: {“type”: “string”, “description”: “The order ID to look up, e.g. ‘4471’”}, }, “required”: [“order_id”], }, } 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 orders_db = { “4471”: {“status”: “shipped”, “carrier”: “UPS”, “eta”: “2 days”}, “4472”: {“status”: “processing”, “carrier”: None, “eta”: None}, } def get_order_status(order_id): return orders_db.get(order_id, {“error”: “No order found with that ID”}) get_order_status_schema = { “name”: “get_order_status”, “description”: ( “Looks up the current status of a customer order by its ID. “ “Use this any time a question depends on current order data “ “rather than general policy information.” ), “input_schema”: { “type”: “object”, “properties”: { “order_id”: {“type”: “string”, “description”: “The order ID to look up, e.g. ‘4471’”}, }, “required”: [“order_id”], }, } The schema is structured metadata: a name, a description, and a definition of the parameters the function expects. Tool use works the same way across most providers: you pass the model a list of these schemas alongside your message, and the model decides on its own whether answering the question requires calling one of them. Executing the Tool and Feeding the Result Back Pass the schema in, and something different happens. Instead of a plain text answer, the response comes back with a stop_reason of tool_use and a content block describing which function the model wants to call and with what
Synchronous vs. Asynchronous Agent Execution: Architecture Patterns for Production
In this article, you will learn how synchronous and asynchronous execution patterns differ architecturally, and how to choose between them when deploying LLM-based agents to…
Descriptors and Controlled Attributes in Python
In this article, you will learn what Python descriptors are and how to use them to build three types of controlled attributes: validated, computed, and…
Choosing the Right Agentic AI Framework for 2026: A Decision-Tree Approach
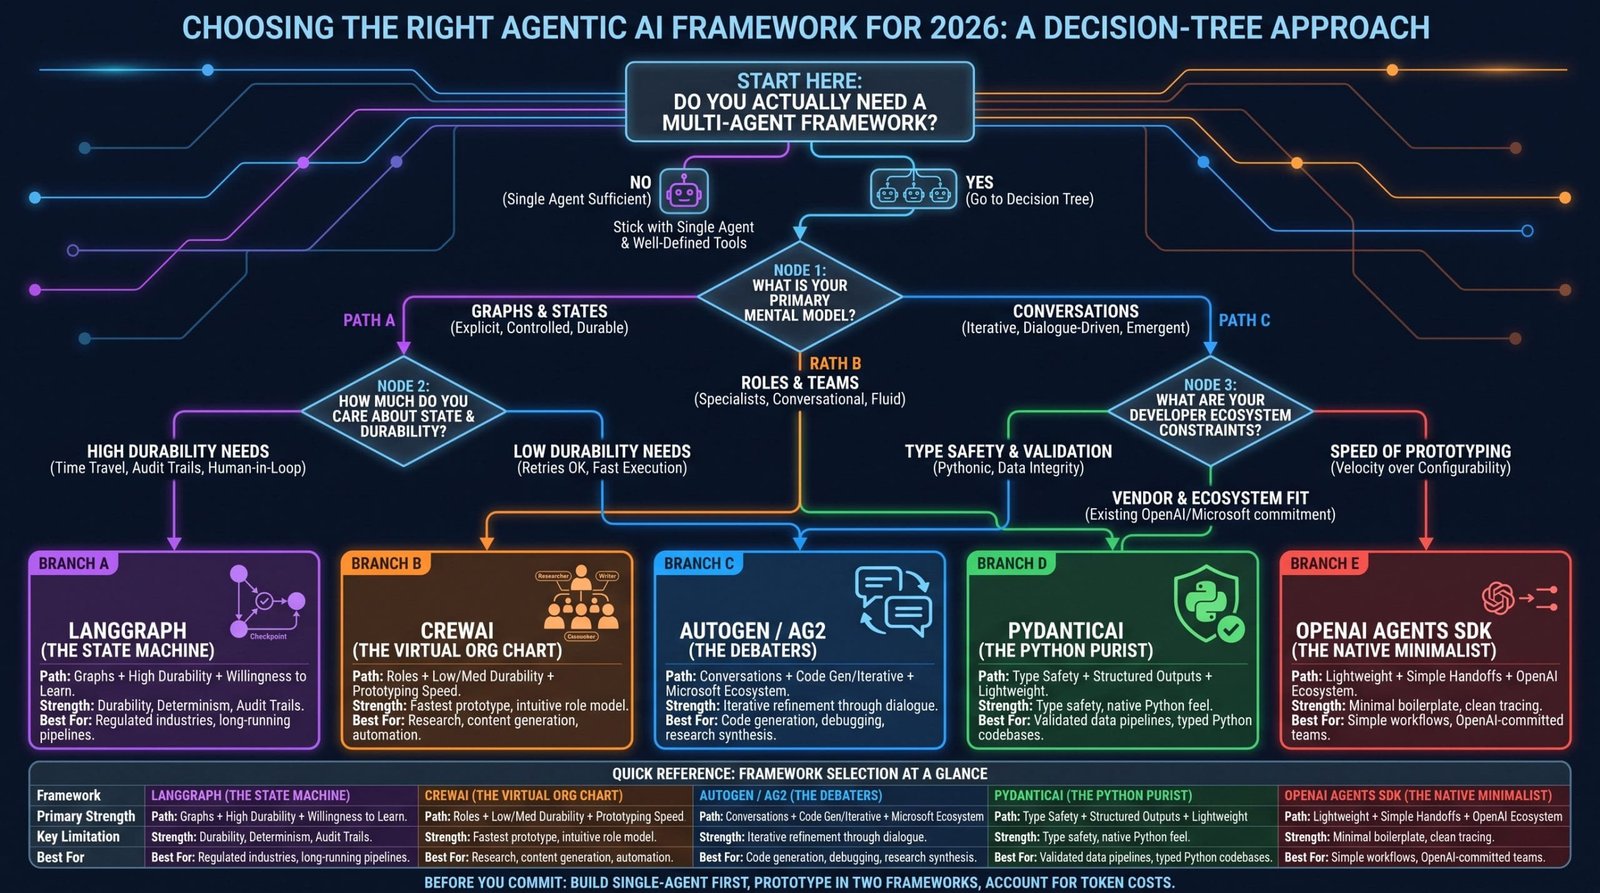
In this article, you will learn how to choose the right agentic AI framework for your production system by working through a structured decision-tree based on your workload’s actual requirements. Topics we will cover include: How to determine whether your task actually requires a multi-agent framework at all. Three key decision nodes — mental model, durability needs, and ecosystem constraints — that narrow the field of candidates. An honest comparison of five major frameworks (LangGraph, CrewAI, AutoGen/AG2, PydanticAI, and the OpenAI Agents SDK), including their best-fit scenarios and watch-out cases. Introduction The agentic AI space has matured fast. What was experimental scaffolding in 2023 is now a crowded category of serious orchestration frameworks, each with strong opinions about how agents should think, coordinate, and fail. Developers facing this choice in 2026 are not dealing with toy projects. They are deciding on the architecture that will shape their production systems for years. The problem is that most framework comparisons measure the wrong things. GitHub stars, benchmark scores, and “easiest to get started” rankings tell you almost nothing about how a framework will behave when your workflow hits an edge case at 2 a.m. on a Sunday. A framework that excels at open-ended collaborative research will fall apart in a tightly regulated compliance pipeline. A framework optimized for strict deterministic branching will feel like bureaucratic overhead for a simple conversational assistant. This guide takes a decision-tree approach: a set of structured questions about your workload that map directly to a framework recommendation, plus an honest look at the trade-offs on each path. Starting Here: Do You Actually Need a Multi-Agent Framework? Before evaluating frameworks, answer this question honestly: does your task require multiple agents at all? The single most common mistake developers make is reaching for orchestration complexity before it’s warranted. A single agent with well-defined tools and a clear system prompt can handle a surprisingly large range of tasks, and it’s dramatically easier to debug, monitor, and reason about. Reach for a multi-agent framework only when a single agent hits a clear limitation. The most common triggers are: The context window fills up before a task completes The task involves genuinely parallel subtasks that don’t depend on each other Different subtasks require radically different system prompts or tool sets You need a separate agent to critique or verify another agent’s output If none of these apply, build a single-agent system first and add orchestration later when you have a concrete reason. If you do need a multi-agent framework, the decision tree below will guide your choice. The Decision Tree: Three Nodes That Narrow the Field Node 1: What Is Your Primary Mental Model? The first question is architectural. How do you naturally think about the work your system needs to do? Option A: You think in graphs and states. Your workflow has defined steps, explicit transitions between them, and you care deeply about what happens when a step fails, needs to be retried, or requires a human to approve before continuing. You might sketch this on a whiteboard as a flowchart with labeled edges. Option B: You think in roles and teams. Your workflow maps naturally to specialist contributors — a researcher, a writer, a reviewer — handing work to each other. The coordination is conversational and the boundaries between responsibilities are somewhat fluid. Option C: You think in conversations. Your workflow is iterative: two or more agents discussing a problem, one generating and the other critiquing, until the output meets a quality threshold. The “structure” emerges from the dialogue rather than being prescribed in advance. Node 2: How Much Do You Care About State and Durability? The second question is about what happens between steps. High durability needs: Your workflow may run for minutes or hours. You need to pause it, inspect its state, resume it, or roll it back. Humans need to approve certain transitions. You need an audit trail for compliance or debugging purposes. If your workflow touches money, medical records, or legal documents, you almost certainly need this. Low durability needs: Your workflow runs in seconds or a few minutes. If it fails, you can simply retry from the beginning. You don’t need to inspect intermediate states. Node 3: What Are Your Developer Ecosystem Constraints? The third question is pragmatic. Type safety and validation: Your team writes Python with strict typing. Data integrity at the boundary of each function is non-negotiable. You want your agent framework to feel like the rest of your codebase. Vendor and ecosystem fit: Your team already uses OpenAI’s API extensively, or you’re building in the Microsoft ecosystem. Tight integration with your existing vendor relationship matters more than framework neutrality. Speed of prototyping: You need to go from idea to a working multi-agent prototype in hours, not days. You’re willing to trade configurability for velocity. The Five Framework Branches Branch A: LangGraph (The State Machine) Path: Graph-based mental model + High durability needs + Willingness to invest in a learning curve LangGraph, now a standalone project within the LangChain ecosystem, models your workflow as an explicit directed graph. Nodes are functions. Edges are transitions. State is a typed dictionary that flows through the graph and can be persisted at any checkpoint. This architectural choice has real consequences. Because state is explicit and serializable, LangGraph supports “time travel”: pausing a workflow mid-execution, inspecting the state at any node, modifying it, and resuming. Human-in-the-loop approvals become a first-class feature rather than an afterthought. Audit trails are built in. LangGraph is the go-to for workflows in regulated industries: banking compliance pipelines, legal document review, medical record processing. Anywhere that “what did the agent decide and why?” is a question you’ll need to answer after the fact, LangGraph gives you the infrastructure to answer it. The trade-off is real, though. LangGraph requires you to be explicit about everything. Defining your state schema, specifying each node, wiring the edges, configuring checkpointers — all of this is code that doesn’t exist in more opinionated frameworks. Teams report that

