In this article, you will learn how to think in terms of vectorized operations using NumPy, replacing slow Python loops with efficient array-level computations. Topics we will cover include: Why Python loops are slow for numeric data and how NumPy’s C-backed engine addresses this. How to apply element-wise operations, boolean masking, and broadcasting to eliminate common loop patterns. How to handle multi-condition branching and axis-based aggregation entirely with NumPy functions. Introduction You already know how to loop in Python. Loops are simple, readable, and they do exactly what they say. The problem is that at scale, Python loops become too slow. At some point, every developer working with numeric data starts looking for a better approach. NumPy’s vectorized operations provide that alternative. Instead of telling Python what to do element by element, you describe the transformation at the array level and let NumPy’s C-backed engine apply it across all elements efficiently. This article teaches vectorized thinking through a set of examples. You’ll see the loop-based version, its vectorized equivalent, and the reasoning behind translating one into the other. You can find the complete code for these examples on GitHub. Understanding Why Loops Are Slow In Python It helps to start by understanding why the loop you are replacing is slow. Python is dynamically typed. Every time you write an operation like x * 2 inside a loop, Python must determine the type of x, find the correct multiplication method, execute it, and create a new Python object for the result. That overhead is insignificant when working with a small number of elements. But when the same operation runs across millions of values, those repeated Python-level operations add up quickly. NumPy arrays work differently. They store elements as raw numbers in a contiguous block of memory, similar to how arrays are stored in C. When you write arr * 2, NumPy passes the entire array to a compiled C routine that applies the operation without Python overhead for each individual item. The computation runs closer to compiled code speed rather than interpreted Python speed. Applying Operations Element By Element A common first step with numeric data is applying the same formula to every value in a list. Consider a simple example: you have a list of product prices and need to apply a 12% tax rate to each item. Loop Version The traditional approach iterates through each price, calculates the taxed value, and appends the result to a new list. prices = [12.99, 45.00, 7.49, 129.99, 3.25, 89.50] taxed = [] for price in prices: taxed.append(round(price * 1.12, 2)) print(taxed) prices = [12.99, 45.00, 7.49, 129.99, 3.25, 89.50] taxed = [] for price in prices: taxed.append(round(price * 1.12, 2)) print(taxed) Output: [14.55, 50.4, 8.39, 145.59, 3.64, 100.24] [14.55, 50.4, 8.39, 145.59, 3.64, 100.24] Vectorized Version The vectorized approach replaces the loop with a single operation on a NumPy array. When you write prices * 1.12, NumPy applies the multiplication to every element automatically. import numpy as np prices = np.array([12.99, 45.00, 7.49, 129.99, 3.25, 89.50]) taxed = np.round(prices * 1.12, 2) print(taxed) import numpy as np prices = np.array([12.99, 45.00, 7.49, 129.99, 3.25, 89.50]) taxed = np.round(prices * 1.12, 2) print(taxed) Output: [ 14.55 50.4 8.39 145.59 3.64 100.24] [ 14.55 50.4 8.39 145.59 3.64 100.24] The output is identical, but the approach scales much better. For large arrays containing millions of prices, the vectorized version can be dramatically faster than the loop-based equivalent. The important mental shift is moving from: “For each price, perform this calculation.” to: “Apply this transformation to the entire array of prices.” The array becomes the unit of computation rather than the individual element. Using Boolean Masking For Conditional Logic Loops often contain if statements that check each value individually. The vectorized equivalent is a boolean mask: an array of True and False values generated from a comparison. A boolean mask can then be used to filter values or update selected elements without writing a loop. Consider a weather monitoring system that records hourly temperatures. You want to flag every reading above 38°C as a heat alert. Loop Version The loop approach checks each temperature value and builds a separate list of alert flags. readings = [34.1, 38.5, 37.2, 39.0, 36.8, 40.1, 35.5] alerts = [] for temp in readings: alerts.append(temp > 38.0) print(alerts) readings = [34.1, 38.5, 37.2, 39.0, 36.8, 40.1, 35.5] alerts = [] for temp in readings: alerts.append(temp > 38.0) print(alerts) Output: [False, True, False, True, False, True, False] [False, True, False, True, False, True, False] Vectorized Version With NumPy, comparing an array directly creates the boolean mask automatically. There is no explicit loop and no repeated append() operation. import numpy as np readings = np.array([34.1, 38.5, 37.2, 39.0, 36.8, 40.1, 35.5]) alerts = readings > 38.0 print(alerts) print(“Alert readings:”, readings[alerts]) import numpy as np readings = np.array([34.1, 38.5, 37.2, 39.0, 36.8, 40.1, 35.5]) alerts = readings > 38.0 print(alerts) print(“Alert readings:”, readings[alerts]) Output: [False True False True False True False] Alert readings: [38.5 39. 40.1] [False True False True False True False] Alert readings: [38.5 39. 40.1] The mask can immediately index back into the original array and return only the values that matched the condition. This pattern is one of the most important ideas in vectorized programming: Compute a mask, then use that mask to select or modify values. It replaces many of the conditional checks you would normally write inside a loop. For conditional assignment, np.where() provides a compact alternative. For example, the following operation sets high temperatures to 38.0 while leaving other values unchanged: np.where(readings > 38.0, 38.0, readings) np.where(readings > 38.0, 38.0, readings) Broadcasting Across Different Array Shapes Broadcasting is NumPy’s mechanism for applying operations between arrays with different shapes without creating unnecessary copies. It can feel more abstract at first, but it removes many nested loops that would otherwise be needed to align data structures manually. Consider a practical example. Imagine you have click-through
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/apple-announces-launch-date-for-iphone-18-check-the-latest-features-cost-and-more-3068705.html” on this server. Reference #18.c4f43717.1787847937.1b5d048e https://errors.edgesuite.net/18.c4f43717.1787847937.1b5d048e
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/gta-6-extended-look-when-and-where-to-watch-in-india-what-to-expect-amid-leak-controversy-3068582.html” on this server. Reference #18.c4f43717.1787808260.160a5f81 https://errors.edgesuite.net/18.c4f43717.1787808260.160a5f81
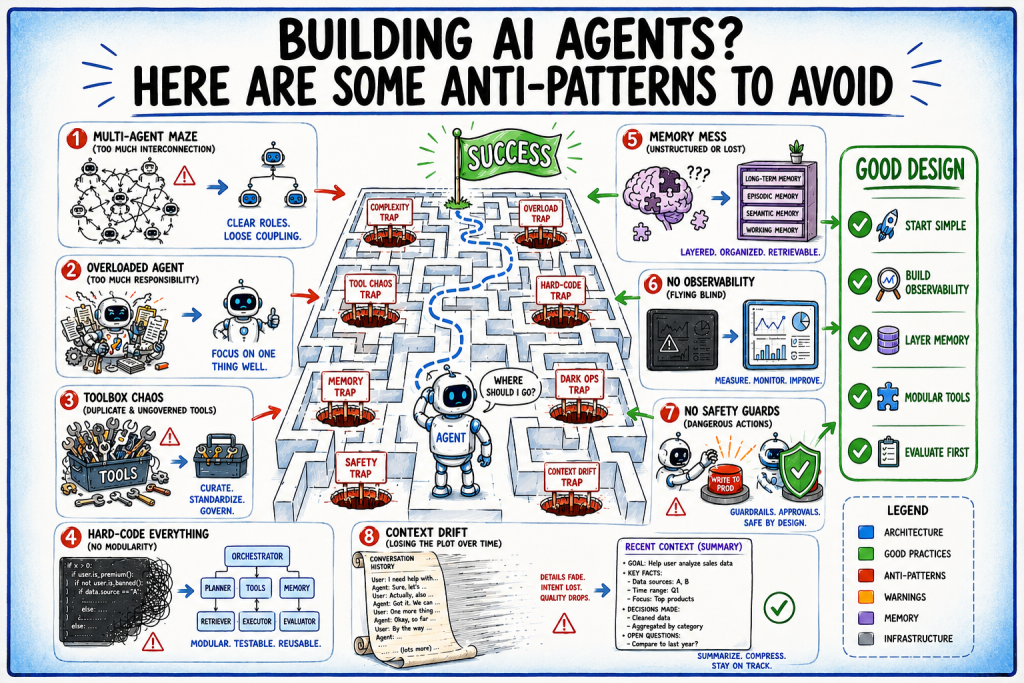
Building AI Agents? Here Are Some Anti-Patterns to Avoid.
In this article, you will learn the architectural and operational anti-patterns that cause AI agent projects to fail, and how to avoid each one. Topics we will cover include: Why agent failures compound differently than failures in simpler, single-response AI systems. The architectural anti-patterns — from premature multi-agent systems to tool sprawl, hardcoded logic, and missing memory design — that make agents brittle as they scale. The operational anti-patterns — including missing observability, ungoverned write access, context drift, and skipped evaluation — that only surface once an agent reaches production. Introduction AI agents fail in predictable ways. The model is rarely the problem; the architecture, the memory design, the tooling decisions, and the way complexity gets introduced are where things go wrong. Most failed agent projects share a handful of structural mistakes that only become visible later, when they’re expensive to fix. Understanding what breaks AI agents — and why — gives you a better mental model for what working agents actually require. An effective approach is to start simple, build for observability, and add complexity only when you can measure the return. The anti-patterns are what happens when teams do the opposite. This article covers: Why agents fail differently from simpler AI systems The architectural mistakes that compound as your system grows The operational mistakes that only surface in production A summary table mapping every anti-pattern to its fix Start here before you start building. Why Agent Failures Hit Harder A language model answers a question. An agentic system solves a task: assessing what to do, choosing tools, acting on results, adjusting when something goes wrong. The reasoning loop is what makes agents powerful, and it’s also what makes them fail in ways that a prompt-and-response system never would. When a chatbot gives a bad answer, the conversation ends. When an agent goes wrong mid-task, however, it keeps going. It might call tools with bad parameters, produce outputs that downstream steps depend on, or loop indefinitely because it can’t recognize that it’s stuck. The blast radius of a bad decision grows with every step. Autonomous agents also accumulate state across steps, which means errors compound. An incorrect tool call in step two affects the context available in step five. A stale memory entry shapes decisions three steps later. By the time something looks wrong to the user, the agent may have already taken several incorrect actions based on a faulty initial assumption. This is why agent failures are different in kind, not just degree. Reaching for Multi-Agent Architecture Too Soon The most common architectural mistake is treating sophistication as a goal. Teams read about multi-agent systems, hierarchical orchestrators, and peer-to-peer collaboration, and design toward those patterns before they’ve validated whether a single agent can solve the problem. Multi-agent systems introduce coordination overhead that compounds cost and debugging difficulty in ways that are hard to anticipate upfront. A few questions worth asking before you go multi-agent: Can a single agent with well-designed tools already solve the problem? Have you measured where the single-agent approach actually breaks down? Does the business value justify the token cost and added complexity? Usually, for a first deployment, a single agent does the job. Start with the simplest thing that could work, measure it, and add layers only when the data shows you need them. Building One Agent That Does Everything A single agent configured with fifteen tools, sprawling instructions, and responsibility for wildly different task types will underperform across all of them. Optimizing for one kind of input hurts performance on others, which is why routing inputs to specialized agents — rather than one general-purpose one — tends to produce better results. The fix isn’t always to add more agents. Often a well-scoped single agent with specialized skills outperforms a bloated general-purpose one. Narrow the responsibility first. If that still isn’t enough, then you have a real case for splitting. Letting the Tool List Sprawl Every tool added to an agent’s context is a tool the model has to reason about when deciding what to do next. A large tool surface increases the chance of the model choosing poorly, inflates prompt size, and makes debugging harder because there are more possible paths through any given task. Too many tools, or tools with overlapping purposes, actively distract agents from pursuing efficient strategies. Keep the tool set minimal and purpose-specific: Tools should be discrete, reusable modules with clear, non-overlapping responsibilities If tools share similar functions, namespace them explicitly so the model can distinguish them If you’re adding tools to handle edge cases, that’s a signal the task scope needs to shrink — not that the tool list needs to grow AI agent architecture anti-patterns Hardcoding Logic Instead of Building for Change Agent systems change constantly in production. A prompt that works today gets revised next week as tools get refactored and model updates shift what’s possible. When an agent’s logic is hardcoded into a monolithic implementation rather than composed from separable components, every one of those changes risks breaking something else. Modular design means prompts in centralized configuration, tools as discrete units, and agents assembled from only the components they need for a given task. Skipping Dedicated Memory Design Many teams design agents the same way they design chatbots: pass the conversation in, get a response out. An agent working a multi-step task needs to know what it did two steps ago, whether a tool call succeeded, and what intermediate results it’s carrying forward. Without a deliberate memory design, context window overflow becomes a production incident rather than a design consideration. A layered approach handles this cleanly: Short-term session memory for current task state and recent tool outputs Long-term memory (typically a vector store) for cross-session context and learned patterns Structured logs for auditability and debugging Build this in from the start. Retrofitting a memory architecture onto a deployed agent is genuinely painful and usually results in a partial rebuild anyway. Shipping Without Observability AI agents are usually non-deterministic systems with opaque reasoning processes. When
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/whatsapp-tests-age-verification-feature-in-india-ahead-of-dpdp-act-implementation-3065292.html” on this server. Reference #18.c4f43717.1786123042.63c65233 https://errors.edgesuite.net/18.c4f43717.1786123042.63c65233
7 Chunking Strategies That Decide Whether Your RAG Works
In this article, you will learn seven distinct chunking strategies for RAG pipelines, how each one works, and when to choose one over another for your specific use case. Topics we will cover include: Why naive fixed-size token chunking destroys semantic meaning and how strategies like sentence-window retrieval and structural chunking preserve it. Advanced approaches including semantic chunking, hierarchical chunking, LLM-driven propositional chunking, and multi-modal table-preserving chunking. What matters beyond chunking strategy in production RAG systems, including index lifecycle management and chunk deduplication. The Naive Approach Doesn’t Work Dumping unstructured text into a fixed-size token window and calling it a Retrieval-Augmented Generation (RAG) pipeline is a recipe for hallucination. RAG is essentially giving an AI an open-book test: the system searches a database for relevant notes, hands them to the large language model (LLM), and the model synthesizes an answer from those notes. But that database is entirely dependent on your chunking strategy — the rulebook used to slice a massive document into smaller pieces that an embedding model can read and store. The naive approach of slicing documents into static 512-token arrays tears semantic boundaries in half, destroying context before the embedding model (the system that translates text into mathematical arrays) even sees it. Sever a negative qualifier from its subject, or split a function definition across two vectors, and the retriever is effectively blind, grabbing the wrong notes for the LLM’s open-book test. One thing worth clarifying before we dig in: chunking (the deterministic or heuristic splitting of text strings) and parsing (extracting logical DOM/AST structures from raw document formats) are not the same thing. Bad parsing guarantees bad chunking, but even perfect parsing needs a solid chunking architecture to survive production query loads. 1. Fixed-Size Token Chunking with Overlap The Concept: Splitting text strictly by raw token counts using a sliding window to catch edge-boundary context. How It Works: A fast tokenizer maps raw text to an integer array, slices it into uniform blocks (e.g. 512 tokens), and overlaps them by a fixed margin (e.g. 50 tokens) before decoding back to text strings for the embedding encoder. Worth Noting: It’s structurally blind. You’ll inevitably slice a try/except block down the middle or separate a pronoun from its antecedent. Overlap mitigates this slightly, but increases vector database bloat and ingestion compute costs linearly with the overlap ratio. When to Use It: When processing homogenous, unstructured log files or flat text streams where structural boundaries don’t exist and ingestion latency is the top priority. 2. Sentence-Window Retrieval (Small-to-Big) The Concept: Embedding a granular chunk to maximize vector search precision, then returning the expanded surrounding context to the LLM during prompt assembly. How It Works: At ingestion, documents are parsed into individual sentences. Each sentence is embedded and stored with a metadata pointer to its surrounding \( k \) sentences. At retrieval time, the vector database returns the top-\( n \) nearest sentences, and the middleware swaps them out for their expanded text windows before hitting the generation model. Worth Noting: Redundant context injection is a real risk here. If two adjacent sentences both clear the top-\( k \) retrieval threshold, your middleware needs graph-based deduplication of the overlapping context windows. Skip that step, and you’ll blow out the LLM context window and trigger inference latency spikes. When to Use It: When domain facts are densely packed and heavily nuanced (e.g. medical literature, legal statutes, etc.) where you need high retrieval precision without losing surrounding context. 3. Document-Aware Structural Chunking The Concept: Splitting documents along their logical markdown or DOM boundaries (H1, H2, paragraphs, list items) rather than arbitrary token limits. How It Works: The pipeline uses parsers to build a tree of the document structure, chunks the leaf nodes (paragraphs and lists), and prepends the parent header hierarchy to each chunk (e.g., H1: Q3 Earnings > H2: Risk Factors > [Chunk]). This preserves global context regardless of where the chunk ends up spatially. Worth Noting: Node sizes are non-deterministic and vary widely. A large sub-section might still exceed your embedding model’s maximum sequence length (often 512 or 1024 tokens for dense encoders), forcing a fallback to token-based chunking, which risks breaking the structural integrity you just paid compute cycles to parse. When to Use It: When ingesting heavily formatted corporate documents, API documentation, or contracts where the header hierarchy inherently defines the semantic payload. 4. Semantic (Embedding-Based) Chunking The Concept: Dynamically determining chunk boundaries by measuring the distance between sequential sentence vectors and splitting when semantic drift exceeds a threshold. How It Works: Slide a sentence-level window across the text, generating lightweight embeddings for each sentence. Calculate the cosine similarity (mathematical closeness) between sentence \( i \) and \( i+1 \). If similarity drops below an empirically tuned hyperparameter \( \epsilon \), insert a hard chunk boundary. That drop signals a topic change. Worth Noting: Ingestion latency and cost increase significantly. You’re forcing a forward pass through an encoder for every single sentence before you generate the final chunk embedding. And \( \epsilon \) is notoriously brittle — nearly impossible to tune globally across heterogeneous document sets. When to Use It: When dealing with transcribed audio, meeting notes, or long-form narrative text that lacks structural formatting but contains distinct, unpredictable thematic shifts. 5. Hierarchical / Parent-Child Chunking The Concept: Creating a tree of chunks where multiple granular child nodes map to a single broad parent node. Retrieve enough children and you get the whole parent. How It Works: Text is chunked at multiple granularities (e.g. 256 tokens and 1024 tokens). The 256-token chunks are embedded and mapped to their 1024-token parent via metadata foreign keys in the vector store. If \( >x\% \) of a parent’s children are retrieved by the Approximate Nearest Neighbor (ANN) search, the query planner executes a merge and swaps the child chunks for the parent chunk. Worth Noting: Managing the parent-child relational mapping in a distributed vector database gets complex fast. Deletes and document updates require cascading invalidations across the tree, and the
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/meta-row-parliamentary-panel-seeks-mark-zuckerberg-apology-in-3-days-3064949.html” on this server. Reference #18.eff43717.1785930145.3a58de10 https://errors.edgesuite.net/18.eff43717.1785930145.3a58de10
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/whatsapp-chaos-several-accounts-in-india-put-under-review-users-access-disrupted-3064618.html” on this server. Reference #18.c4f43717.1785901097.4690c568 https://errors.edgesuite.net/18.c4f43717.1785901097.4690c568
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/galaxy-s27-series-leak-reveals-four-phones-different-cameras-for-each-3064705.html” on this server. Reference #18.54fdd417.1785879195.21b71cad https://errors.edgesuite.net/18.54fdd417.1785879195.21b71cad
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/vivo-s2-launching-in-india-on-august-6-heres-what-to-expect-3064709.html” on this server. Reference #18.eff43717.1785860188.356859c2 https://errors.edgesuite.net/18.eff43717.1785860188.356859c2