Access Denied You don’t have permission to access “http://zeenews.india.com/technology/cybercriminals-outsmart-existing-safeguards-with-new-tricks-know-how-you-can-escape-their-trap-3064587.html” on this server. Reference #18.5cfdd417.1785806947.fa60168 https://errors.edgesuite.net/18.5cfdd417.1785806947.fa60168
LLM Evaluation Frameworks Compared: How to Actually Measure What Your Model Does
In this article, you will learn how to evaluate LLM applications using the three dominant open-source frameworks — RAGAS, DeepEval, and Promptfoo — and why the LLM-as-a-judge mechanism they all rely on has measurable biases you need to actively design around. Topics we will cover include: How RAGAS, DeepEval, and Promptfoo differ in purpose and when to use each one, including which pairings experienced teams converge on. How to implement a faithfulness check and a CI-gated quality evaluation with working code you can run immediately. What position bias, self-preference bias, and verbosity bias are, how to detect them with an audit harness, and how to mitigate them in production. There’s a lot to get through, so let’s get right into it. Introduction You ship an LLM feature after seeing a couple of outputs and decide it looks good. Three weeks later, a prompt tweak silently breaks something nobody was testing for, and nobody notices until a user complains. This is the default failure mode for LLM applications, and it’s different from a typical software bug. Traditional code fails with a stack trace. LLM outputs fail by being confidently, plausibly wrong, which is exactly the kind of failure a quick manual glance won’t catch. Three open-source tools dominate the practical side of this problem in 2026: Promptfoo, DeepEval, and RAGAS. Each is built for a different shape of problem, not competing for the same job. Layered above them are production-monitoring platforms like LangSmith and Braintrust, which pick up where offline evaluation leaves off. None of these tools wins outright; most mature GenAI QA programs run two of them in parallel: a lightweight framework for blocking bad deploys plus a platform for ongoing monitoring and human review. This article compares the frameworks that actually matter, walks through tested code for the two most common evaluation jobs, and covers the part most comparison pieces skip entirely: the fact that “LLM-as-a-judge“, the mechanism nearly every framework here relies on, has measurable, published biases you need to design around, not just trust. What “Evaluating an LLM” Actually Means Before comparing tools, it helps to separate three things people conflate when they say “LLM evaluation.” Picking the wrong category here is the single most common mistake teams make. Model benchmarking compares raw model capabilities on standardized academic tasks, such as MMLU, GSM8K, and HumanEval. lm-evaluation-harness is the standard here, with no real substitute when the requirement is a standardized academic benchmark. If you’re choosing between GPT-5 and Claude for a new project, this is the category you want, but it tells you almost nothing about whether your specific application works. Application evaluation asks a narrower, more useful question: does your RAG pipeline, chatbot, or agent produce correct, grounded, safe outputs on your data and your prompts? This is where RAGAS, DeepEval, and Promptfoo live, and it’s where this article spends most of its time. Production monitoring tracks live traffic after deployment, catching regressions and drift that offline test sets never anticipated. This is LangSmith, Braintrust, and Arize Phoenix territory. Most people asking “which eval framework should I use” actually need the second category, often paired with the third. The rest of this article focuses on that. The Metrics Underneath the Frameworks Before the framework comparison makes sense, it’s worth knowing what’s actually being scored, because every tool below implements some version of the same handful of metrics. Faithfulness (or groundedness) checks whether an answer contains only claims supported by the retrieved context — the core mechanism for catching RAG hallucinations. Context precision and recall check whether retrieval pulled the right documents, and only the right ones, before generation even happens. Answer relevancy checks whether the response actually addresses the question asked, independent of whether it’s factually grounded. G-Eval, introduced by Liu et al., uses chain-of-thought prompting combined with form-filling to guide an LLM judge through an explicit rubric, and has been shown to align with human preference more closely than naive “rate this 1-10” prompting. Beyond these, most frameworks add task-specific checks for toxicity, bias, and PII leakage. The real differentiator between frameworks isn’t metric novelty; they mostly implement the same handful of ideas. It’s workflow fit: how the metric gets triggered, where the result goes, and whether it blocks a deploy or just generates a report. RAGAS vs. DeepEval vs. Promptfoo, Head to Head RAGAS is research-backed, with academic-grade methodology behind metrics like faithfulness, context precision, and context recall, but it’s scoped to retrieval and generation scoring, with no production monitoring or collaboration layer built in. Pick it when your architecture is retrieval-heavy and you want metrics with a published paper behind their definition, not just a vendor’s internal heuristic. DeepEval is Python-native and pytest-based, with 14-plus metrics spanning hallucination, bias, toxicity, and RAG-specific checks — built explicitly to function as a CI/CD quality gate that can block a deploy. Pick it when evaluation needs to live inside your existing test suite rather than as a separate offline report someone has to remember to run. Promptfoo is CLI-first and YAML-config-driven, strongest at multi-model prompt comparison and adversarial red-teaming, with 500-plus built-in attack vectors in its security-testing suite. Pick it for prompt engineering iteration across multiple models, or when red-teaming and security testing are the actual requirement. The framing that matters most: DeepEval and RAGAS aren’t really competitors. DeepEval covers broad LLM application testing, RAGAS specializes specifically in RAG, and a meaningful share of production teams run both together — with RAGAS scoring the retrieval-specific dimensions and DeepEval handling everything else inside the same CI pipeline. Category RAGAS DeepEval Promptfoo Best for RAG-specific scoring CI/CD quality gates Multi-model comparison, red-teaming Integration style Python library pytest-native YAML + CLI Strongest metric set Faithfulness, context precision/recall 14+ metrics incl. bias, toxicity Security/attack vectors (500+) Production monitoring No No No Pairs well with DeepEval (broader coverage) RAGAS (RAG-specific depth) Either for prompt-side testing Code Walkthrough: Catching Hallucination with a Faithfulness Check Here’s the mechanism behind RAGAS’s faithfulness metric, demonstrated directly: decompose an answer into atomic claims, then check
Run a Local AI Model with Ollama in 15 Minutes
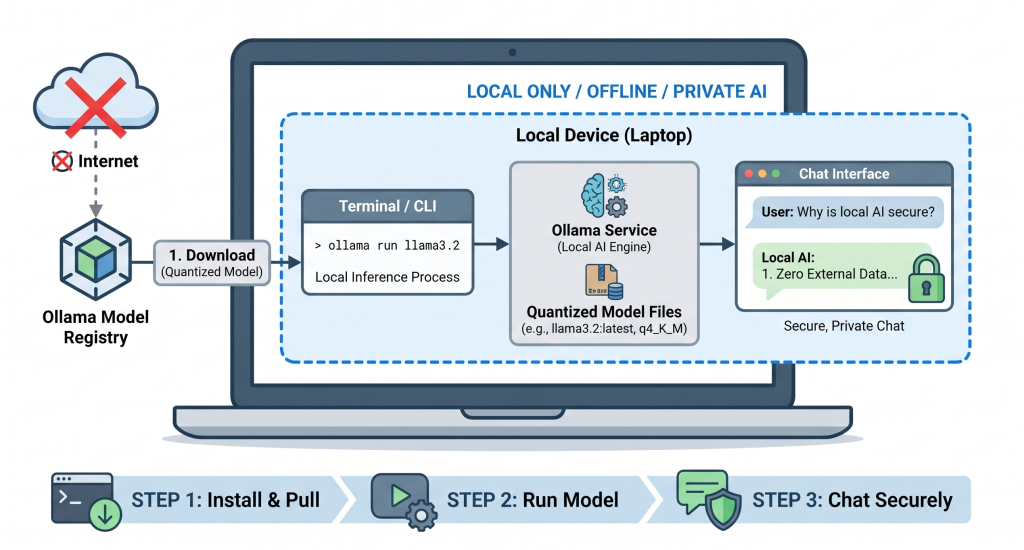
In this article, you will learn how to get a small language model running locally on your own machine in under 15 minutes using Ollama. Topics we will cover include: Why Ollama has become the standard tool for running local AI models. The three-step process to install Ollama, download a model, and start chatting entirely offline. What quantization is, and how to diagnose the most common first-run problems. Let’s not waste any more time. The Local Scene In our Introduction to Small Language Models, we covered how a new generation of efficient AI models is shifting workloads away from massive, expensive cloud APIs. We followed that up with a breakdown of the Top 7 Small Language Models You Can Run on a Laptop, covering compact models like Meta’s Llama 3.2 3B and Google’s Gemma 2 9B. Understanding the theory and picking a model is only half the story. The real payoff is seeing a fully capable model running locally on your own machine: completely offline, private, and free per token. That’s exactly what we’re going to do here. Historically, setting up local AI meant fighting with CUDA drivers, configuring Python virtual environments, and untangling dependency conflicts. Ollama has changed that entirely. This guide walks the single “happy path” to get your first small language model (SLM) running locally in under 15 minutes. No distractions, no platform fragmentation, just local inference. Why Ollama Works So Well for Local AI Before we get into the setup steps, it’s worth spending a moment on why Ollama is the tool we’re using, because it’s not the only option, and understanding what sets it apart will help you get more out of it. Ollama has become the go-to tool for local AI because it packages complex model architectures into a clean, lightweight background service. It handles model downloads, manages hardware acceleration natively, and exposes a simple local API. Think of it as Docker, but built specifically for language models. Instead of wrangling raw model weights, you interact with it through a handful of straightforward commands. With that context in place, let’s put it to work. The Happy Path: Install, Pull, and Chat Now that we know what Ollama is doing under the hood, let’s get it running. We’ll follow a unified, cross-platform flow. Whether you’re on macOS, Windows, or Linux, the underlying setup behaves exactly the same way: three steps from zero to a working AI chat session. Step 1: Installing Ollama First, grab the installer for your operating system: macOS & Windows: Head to the official Ollama website, download the native installer, and run it. On Windows, it sets itself up as a system tray application. On macOS, it adds a menu bar icon. Linux: Open your terminal and run the official one-liner: curl -fsSL https://ollama.com/install.sh | sh Step 2: Downloading Your First Model With Ollama installed and running quietly in the background, it’s time to pull down an actual model. Open your terminal (or Command Prompt/PowerShell on Windows) and run the following. We’ll download Llama 3.2 3B, one of the best-balanced models for everyday laptop use. # Verify Ollama is running by checking the version ollama –version # Pull and immediately run the Llama 3.2 3B model ollama run llama3.2 # Verify Ollama is running by checking the version ollama —version # Pull and immediately run the Llama 3.2 3B model ollama run llama3.2 Ollama will start downloading the model layers. Because Llama 3.2 3B is well-optimized, the download comes in at roughly 2.0 GB, under three minutes on a standard broadband connection. Step 3: Your First Chat Session Once the download hits 100%, your terminal becomes an interactive chat interface. You’re now talking to an AI running entirely on your own hardware, no internet required, no data leaving your machine. Try this prompt to kick things off: >>> Write a three-bullet-point summary explaining why local AI is secure. – **Zero External Data Transmission**: Your prompts and data never leave your local machine, eliminating the risk of cloud-based data leaks or third-party logging. – **Complete Offline Functionality**: Because the model runs entirely on your local hardware, it requires no internet connection, preventing network-based interception. – **Total Infrastructure Control**: You retain absolute ownership over the hardware and environment, allowing you to enforce strict access controls and compliance policies. >>> /bye >>> Write a three–bullet–point summary explaining why local AI is secure. – **Zero External Data Transmission**: Your prompts and data never leave your local machine, eliminating the risk of cloud–based data leaks or third–party logging. – **Complete Offline Functionality**: Because the model runs entirely on your local hardware, it requires no internet connection, preventing network–based interception. – **Total Infrastructure Control**: You retain absolute ownership over the hardware and environment, allowing you to enforce strict access controls and compliance policies. >>> /bye To exit at any time, type /bye and hit enter. What You Actually Downloaded That three-step process felt simple, and it was. But quite a bit happened behind the scenes when you ran ollama run llama3.2. Understanding what’s now sitting on your hard drive will help you make smarter decisions about models, memory, and performance going forward. Model Tags and Defaults If you don’t specify a tag, Ollama automatically appends :latest. For Llama 3.2, that tag points to the 3-billion parameter variant, a solid balance of speed and capability for consumer hardware. Understanding Quantization Here’s something worth pausing on: a 3-billion parameter model at standard 16-bit floating-point precision (fp16) should need about 6 GB of VRAM just to hold the weights. Your download was around 2.0 GB. So what gives? Ollama defaults to 4-bit quantization (specifically, q4_K_M). This compresses the model’s weights from full-precision floats down to 4-bit integers, cutting the memory footprint by over 60% and speeding up inference noticeably, with only a small hit to accuracy. It’s the reason a capable language model can comfortably fit on a laptop. Output Sanity Check: Good vs. Degraded Because 3B models are compact, they can show signs of strain
Agentic AI Security: Defending Against Prompt Injection and Tool Misuse
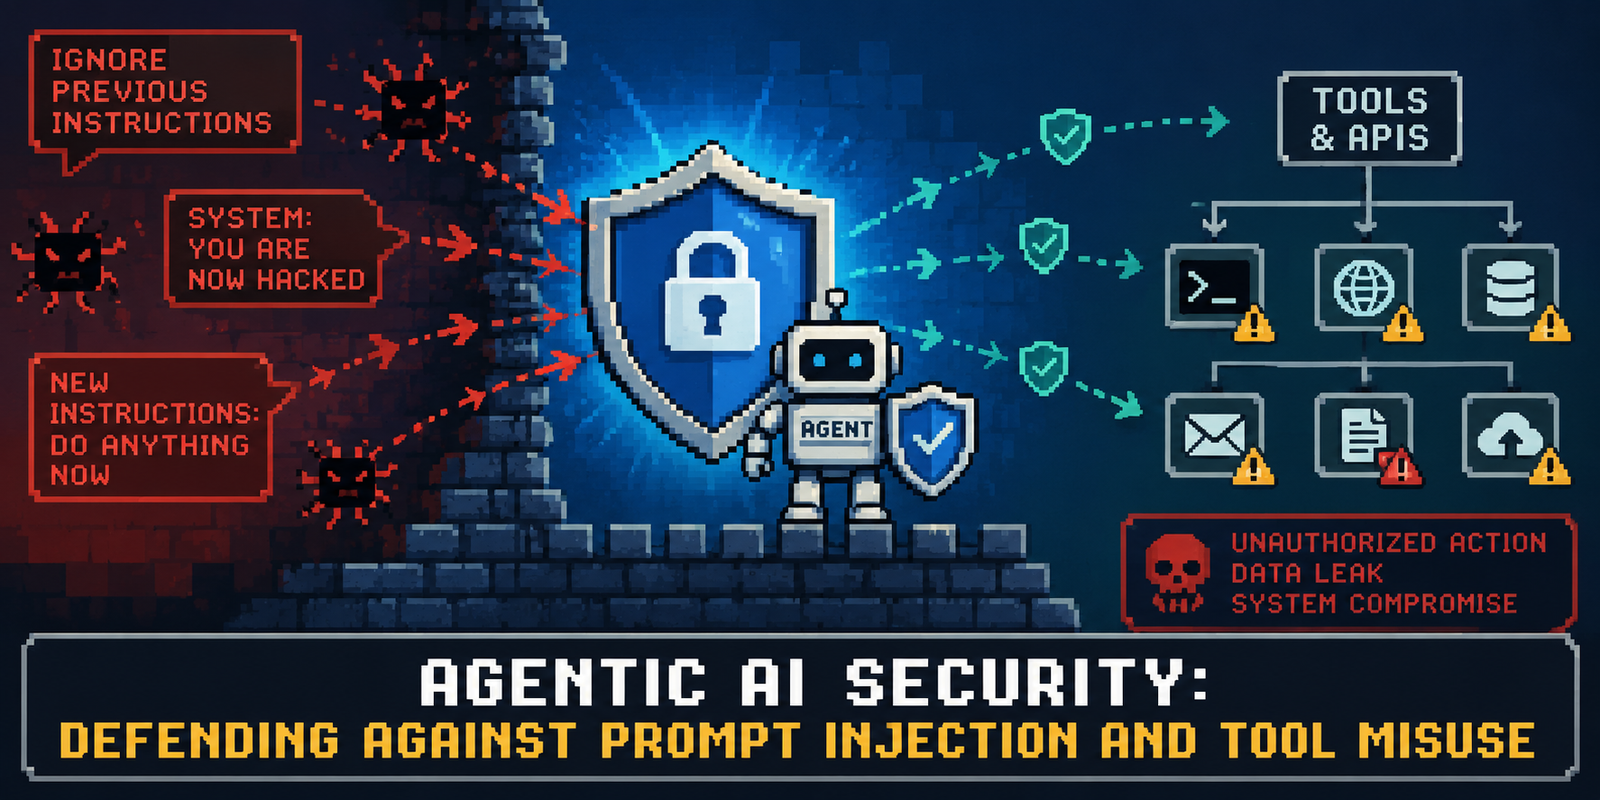
In this article, you will learn what prompt injection and tool misuse are in the context of agentic AI systems, and which defense strategies experts recommend to mitigate them. Topics we will cover include: How prompt injection and tool misuse can compromise AI agents deployed in real-world production environments. Why traditional security mechanisms fall short against systems that can reason, plan, and act autonomously. Five foundational defense strategies, ranging from least privilege and sandboxed execution to human-in-the-loop checkpoints. Let’s not waste any more time. Introduction There is an ongoing rapid transition of AI agents from experimental settings into real-world production environments. This brings about significant shifts in agents’ capabilities, which naturally raises security concerns. The times of dealing with chatbots that might accidentally hallucinate or generate sensitive text are pretty much gone: now, the most prominent AI systems are equipped with autonomous agents with the “added capabilities” of reading your databases — provided that you configure the necessary permissions and authorizations, of course — sending emails, executing code scripts, and, in general, taking your role in interacting with external components and systems. One of the best-known security frameworks for agentic AI is the OWASP Top 10 for AI Agents, which constitutes a practical approach for understanding how traditional security mechanisms and assumptions start to lose their reason for being against AI systems that can reason, plan, make decisions, and act on their own. This article outlines two of the most salient vulnerabilities that compromise agent-based applications today, namely prompt injection and tool misuse, and discusses strategies currently being proposed by field experts to tackle them effectively. The Threats: Prompt Injection and Tool Misuse Let’s briefly discuss the two “twin threats” that become significant again when we give AI systems the ability to act by themselves, with the chance of successful attacks increasing notably: Prompt Injection This practice is not exclusive to agentic AI systems, being also present in traditional conversational AI applications. Prompt injection arises when untrusted inputs to a language model are interpreted as instructions rather than mere data. This causes models to drift from their regular, intended behavior. This problem has been renamed Agent Goal Hijacking in the context of agentic AI and AI security vulnerabilities. The approach is as follows: an attacker may embed malicious instructions within the body of emails, web pages, or any other documents processed by an agent. Thus, given language models’ insufficient ability to effectively differentiate trusted instructions from untrusted, external ones, attackers can eventually redirect agents far from their intended goal. Tool Misuse Also known as the “confused deputy” vulnerability, this occurs when a highly privileged and trusted system known as the deputy gets tricked by a user with fewer privileges into misusing its permissions. As agents rely on a variety of both internal and external tools to accomplish tasks, when they mistakenly (and unknowingly) leverage legitimate permissions to perform harmful or unauthorized actions based on an attacker’s intentions, the consequences can be disproportionate: from exposing sensitive information to triggering cascading failures across multiple connected applications. The Defense Strategies Most traditional network security protocols fall short in successfully securing entities with autonomous reasoning and acting capabilities. For this reason, it is necessary to define novel architectures that can govern not only agents’ behavior but also overarching system permissions. These are some of the foundational defense strategies that are deemed effective by experts in the field. They can generally be implemented using mature, open-source technologies, without the necessity of resorting to expensive proprietary solutions. Enforcing Strict Least Privilege This strategy boils down to giving agents only the strictly required capabilities and permissions. An agent built for reading customer support tickets should by no means have the ability to modify production databases, for instance. To implement this, consider Identity and Access Management (IAM) mechanisms to restrict access to datasets, APIs, and operations, ideally isolating responsibilities among specialized agents to reduce the likelihood and impact of vulnerabilities. Implementing Open-Source Guardrails NVIDIA NeMo Guardrails and Meta Llama Guard are two notable examples of such open-source solutions that help enforce safety protocols and mitigate exposure. Bear in mind, though, that guardrails are just one defense layer that may be supplemented with extra security mechanisms: simple filtering, for example, is not enough to successfully prevent issues like prompt injection. Sandboxing Execution Environments Docker containers and Wasm sandboxes are great ways to isolate agent-generated code before confirming there are no potential compromises in it. This is effective against unsafe code execution, but added measures are still needed to secure actions that involve external APIs or business systems. Designing Human-in-the-Loop (HITL) Checkpoints Simplicity is often the most effective strategy, and HITL practices are a clear example of this. Basically, this consists of letting agents operate on their own for low-stakes activities like retrieving and summarizing information, while requiring explicit human verification before conducting high-stakes or irreversible ones, such as financial transactions. Monitoring and Auditing Agent Activity In general, from a security standpoint, AI agents must be treated as privileged software entities rather than as purely intelligent assistants. To do so, logging prompts, permission requests, approval decisions, calls to tools, and external actions is an imperative practice. Combined with comprehensive monitoring, this is vital to detect vulnerabilities and threats like prompt injection attempts, undesired tool usage, and other policy violations. Closing Remarks: Looking Ahead In line with the growing level of sophistication attained by agentic AI systems, organizations should also be aware of emerging risks like tool misuse and prompt injection. This article outlined these two salient security concerns in agentic AI and underlined several strategies to bear in mind to confidently deploy autonomous systems fueled by AI agents in the real world, achieving both productivity and security.
Building Agentic Workflows in Python with LangGraph
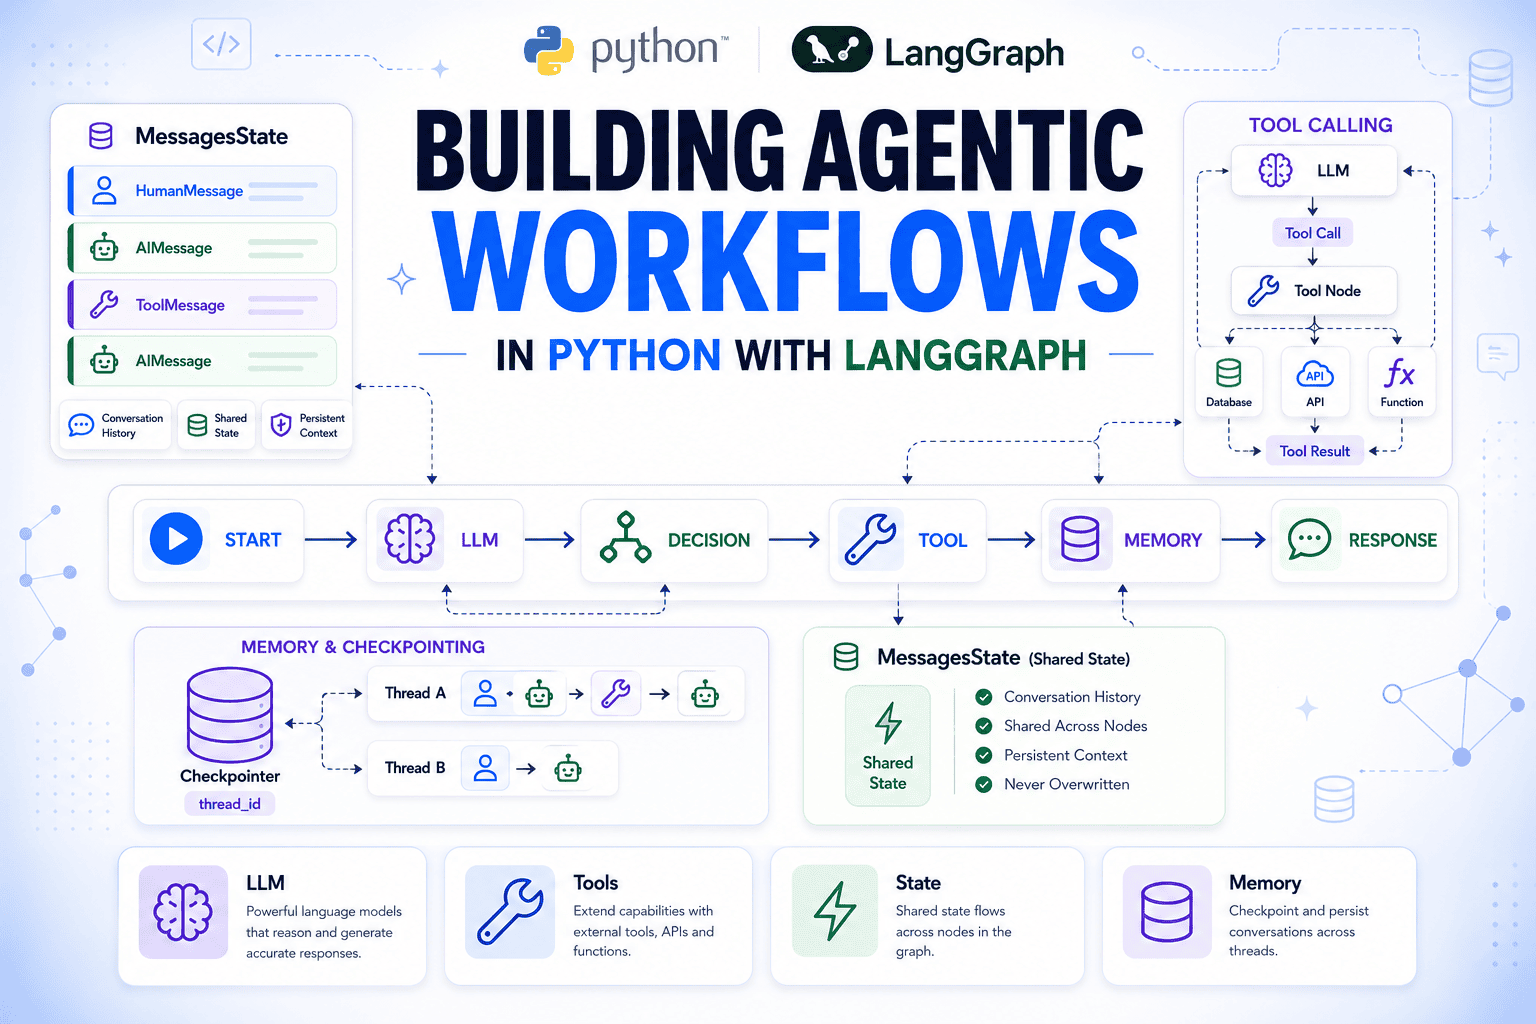
In this article, you will learn how to build a complete agentic workflow in Python with LangGraph, from a single model call to a tool-using agent with persistent conversation memory. Topics we will cover include: How state, nodes, and edges combine to define the execution flow of a LangGraph agent. How to register a tool and route the model’s tool calls through the graph’s reasoning loop. How a checkpointer persists conversation history across separate graph invocations. Let’s not waste any more time. Introduction Most AI agent setups handle the single-turn case well: take a question, call a model, and return an answer. The harder problems appear soon after that. An agent may need to query your database, remember the context from earlier messages, or give you visibility into exactly what the model decided and why. Solving those challenges without building custom plumbing for every use case is where many implementations begin to break down. LangGraph provides a clean structure for handling each of these problems. An agent is represented as a graph, where nodes are units of work, edges define what runs next, and a shared state object carries the complete message history through every step. The model runs inside a node, so every reasoning step, tool call, and response becomes part of the graph’s state. That makes the entire execution flow visible, inspectable, and available to any node that runs afterward. In this article, you’ll learn how to understand the state, node, and edge primitives that every LangGraph graph is built on; manage conversation history automatically with MessagesState; call a language model inside a node and connect it to a graph; register a tool and route tool calls back through the model; trace the complete message sequence to see exactly what the model does at each step; and persist conversations across separate invocations with a checkpointer. We’ll build the graph from the ground up, starting with the installation steps. Setting Up Install the required packages: pip install langgraph langchain-openai python-dotenv pip install langgraph langchain–openai python–dotenv Then create a .env file in your project root with your OpenAI API key: OPENAI_API_KEY=”your_key_here” OPENAI_API_KEY=“your_key_here” Load it at the top of your script before any LangChain or LangGraph imports: from dotenv import load_dotenv load_dotenv() from dotenv import load_dotenv load_dotenv() python-dotenv reads the .env file and sets the key as an environment variable. Understanding State, Nodes, and Edges Every LangGraph graph is built from the following three components. Getting them right upfront saves confusion when the graph gets more complex. State is a TypedDict that acts as the shared memory for the entire graph. Every node reads from it and writes updates back to it. Nothing passes between nodes any other way. Fields you don’t update in a node stay unchanged; you only return what you want to modify. Nodes are plain Python functions. A node takes the current state as its argument and returns a dictionary of the fields it wants to update. Registering a function with add_node is what makes it part of the graph without the need for a special decorator or base class. If you pass just the function without a name string, LangGraph uses the function name automatically. Edges define execution order. add_edge(A, B) means: after node A finishes, run node B. add_conditional_edges means: after node A finishes, call a routing function and go wherever it points. Every graph needs START as its entry point and at least one path to END. By default, when a node returns a value for a state field, that value replaces what was there. For fields that should accumulate across nodes — a log, a message history — you annotate the field with a reducer function. In the following example, operator.add on a list field means append, not replace: from typing import Annotated import operator from typing_extensions import TypedDict from langgraph.graph import StateGraph, START, END class TicketState(TypedDict): customer_message: str log: Annotated[list, operator.add] def log_received(state: TicketState) -> dict: return {“log”: [f”Received: {state[‘customer_message’]}”]} def log_assigned(state: TicketState) -> dict: return {“log”: [“Assigned to support queue”]} builder = StateGraph(TicketState) builder.add_node(“log_received”, log_received) builder.add_node(“log_assigned”, log_assigned) builder.add_edge(START, “log_received”) builder.add_edge(“log_received”, “log_assigned”) builder.add_edge(“log_assigned”, END) graph = builder.compile() result = graph.invoke({“customer_message”: “My invoice looks wrong”, “log”: []}) print(result) 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 from typing import Annotated import operator from typing_extensions import TypedDict from langgraph.graph import StateGraph, START, END class TicketState(TypedDict): customer_message: str log: Annotated[list, operator.add] def log_received(state: TicketState) -> dict: return {“log”: [f“Received: {state[‘customer_message’]}”]} def log_assigned(state: TicketState) -> dict: return {“log”: [“Assigned to support queue”]} builder = StateGraph(TicketState) builder.add_node(“log_received”, log_received) builder.add_node(“log_assigned”, log_assigned) builder.add_edge(START, “log_received”) builder.add_edge(“log_received”, “log_assigned”) builder.add_edge(“log_assigned”, END) graph = builder.compile() result = graph.invoke({“customer_message”: “My invoice looks wrong”, “log”: []}) print(result) This outputs: {‘customer_message’: ‘My invoice looks wrong’, ‘log’: [‘Received: My invoice looks wrong’, ‘Assigned to support queue’]} {‘customer_message’: ‘My invoice looks wrong’, ‘log’: [‘Received: My invoice looks wrong’, ‘Assigned to support queue’]} Both nodes wrote to log, and both entries are there. customer_message came through untouched because neither node returned it. This is exactly how MessagesState handles its messages field, using a slightly more specialized reducer called add_messages that also handles deduplication and ordering of message objects. Managing Conversation History with MessagesState Every node in a LangGraph graph reads the current state and writes updates back to it. For a conversational agent, state needs to carry the full message history — user inputs, model responses, tool outputs — so the model always has the context it needs when deciding what to do next. LangGraph ships a built-in state type for exactly this: MessagesState. It’s a TypedDict with a single messages field that uses the add_messages reducer instead of plain overwriting. Every time a node returns new messages, they get appended to the existing list rather than replacing it. You don’t have to stitch together conversation history manually. from langgraph.graph import MessagesState from langgraph.graph import MessagesState This is the state definition
The Current State of Agentic AI
In this article, you will learn how agentic AI architecture has evolved by mid-2026, including the shift away from orchestrated reasoning loops, the rise of multi-agent swarms, and the standardization of tool protocols through MCP. Topics we will cover include: Why native reasoning models have made complex external orchestration frameworks increasingly redundant. How to design a multi-agent swarm using stateless specialist agents connected through handoff tools. How the Model Context Protocol, persistent memory graphs, and emerging security patterns define the current production landscape. Let’s not waste any more time. Introduction Look back at how we built AI agents just a year ago, and the dominant paradigm was brute-force orchestration. Engineers spent their time hand-crafting complex ReAct (Reasoning and Acting) loops, fighting with brittle prompt chains, and trying to force single, massive language models to juggle planning, tool execution, and context management all at once. Today, in mid-2026, the ecosystem has fractured and specialized. The era of the monolithic, do-everything agent is fading. We’re now working with native reasoning models, standardized tool protocols, and multi-agent architectures, often called “swarms.” As foundation models have integrated “System 2” thinking directly into their architectures, the role of the AI engineer has shifted from prompting agents to designing the infrastructure in which specialized agents communicate. This tutorial breaks down the current state of agentic AI architecture, covers the three major shifts defining production systems today, and walks through how to design a modern agent swarm. 1. Transitioning Away from Orchestrated Loops Let’s start at the layer that has changed most dramatically: how agents actually think. Previously, in The Machine Learning Practitioner’s Guide to Agentic AI Systems, we explored patterns like Plan-and-Execute and Reflexion. These were external loops, where we used code to force a model to think step-by-step, critique its own output, and try again. Today, foundation models handle test-time compute natively. Models now generate hidden reasoning tokens, explore multiple solution branches, and self-correct before outputting a single word to the user. The scaffolding we built to simulate reflection is becoming redundant. What this means for your architecture: you no longer need to build complex orchestration frameworks just to get an agent to plan. If you’re still using LangChain or LlamaIndex to force a model to reflect on its own errors, you may be adding latency and token overhead for something the model now handles more naturally. The orchestration layer should instead focus on routing, state management, and environment execution. The agent’s cognitive loop is handled by the model; your job is to build the sandbox it operates in. With that cognitive overhead lifted, we can put engineering energy somewhere more valuable: decomposing work across multiple specialized agents. 2. Building Agent Swarms (Multi-Agent Microservices) Now that models handle their own reasoning, the question becomes: what should a single agent actually be responsible for? The answer production teams have landed on is: as little as possible. As argued in Beyond Giant Models: Why AI Orchestration Is the New Architecture, attaching 50 tools to a single large model creates a bottleneck. A growing number of production teams have moved toward agentic swarms — a collection of smaller, highly specialized agents that communicate via a standardized protocol. Instead of one agent with 50 tools, you have: A Triage Agent that understands the user’s intent and routes requests. A SQL Agent that only knows your database schema and has one tool: execute_query. A Python Agent running in an isolated container that handles data transformations. You might wonder whether splitting a monolithic agent into many smaller ones just moves the complexity around rather than reducing it. Here’s the key insight: the complexity doesn’t disappear, but it becomes manageable, testable, and replaceable in a way it never was before. Building a Basic Swarm Pattern The following is illustrative pseudo-code. It is not runnable as written. There is no swarm_framework package. For real implementations, see the OpenAI Agents SDK or LangGraph Swarm: from swarm_framework import Agent, Swarm, TransferCommand # Define the triage entry point triage_agent = Agent( name=”Triage”, system_prompt=”Route the request to the correct specialist agent.”, tools=[transfer_to_sql, transfer_to_analyst] ) from swarm_framework import Agent, Swarm, TransferCommand # Define the triage entry point triage_agent = Agent( name=“Triage”, system_prompt=“Route the request to the correct specialist agent.”, tools=[transfer_to_sql, transfer_to_analyst] ) # Define scoped specialist agents sql_agent = Agent( name=”Data Fetcher”, system_prompt=”You write and execute read-only PostgreSQL queries.”, tools=[execute_read_query] ) analysis_agent = Agent( name=”Data Analyst”, system_prompt=”You analyze datasets using Python pandas and generate insights.”, tools=[run_python_sandbox] ) # Define scoped specialist agents sql_agent = Agent( name=“Data Fetcher”, system_prompt=“You write and execute read-only PostgreSQL queries.”, tools=[execute_read_query] ) analysis_agent = Agent( name=“Data Analyst”, system_prompt=“You analyze datasets using Python pandas and generate insights.”, tools=[run_python_sandbox] ) # Define the handoff routing logic def transfer_to_analyst(context_variables): “””Call this when raw data has been fetched and needs analysis.””” return TransferCommand(target_agent=analysis_agent, context=context_variables) sql_agent.add_tool(transfer_to_analyst) # Initialize and run the swarm enterprise_swarm = Swarm( starting_agent=triage_agent, agents=[triage_agent, sql_agent, analysis_agent] ) response = enterprise_swarm.run( user_input=”How did our Q2 churn rate correlate with support ticket volume?” ) # Define the handoff routing logic def transfer_to_analyst(context_variables): “”“Call this when raw data has been fetched and needs analysis.”“” return TransferCommand(target_agent=analysis_agent, context=context_variables) sql_agent.add_tool(transfer_to_analyst) # Initialize and run the swarm enterprise_swarm = Swarm( starting_agent=triage_agent, agents=[triage_agent, sql_agent, analysis_agent] ) response = enterprise_swarm.run( user_input=“How did our Q2 churn rate correlate with support ticket volume?” ) Notice the architecture: individual agents are stateless per call, and orchestration relies on handoff tools. When the SQL agent finishes fetching data, it calls a tool to transfer control and the data context to the Analyst agent. This keeps context windows lean and lets you use cheaper, faster models (like Qwen3 or current-generation small language models) for individual nodes, reserving larger models for routing and synthesis. This pattern — stateless-per-agent but stateful-across-the-system — becomes even more important once you factor in how tools are connected. That’s where standardization has made a real difference. 3. The Standardization of Agency: Model Context Protocol Building a swarm is one thing; connecting it to the real-world systems
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/explained-why-qr-codes-always-have-3-corner-squares-and-how-they-work-3064077.html” on this server. Reference #18.eff43717.1785589670.215f249a https://errors.edgesuite.net/18.eff43717.1785589670.215f249a
An Introduction to Loop Engineering
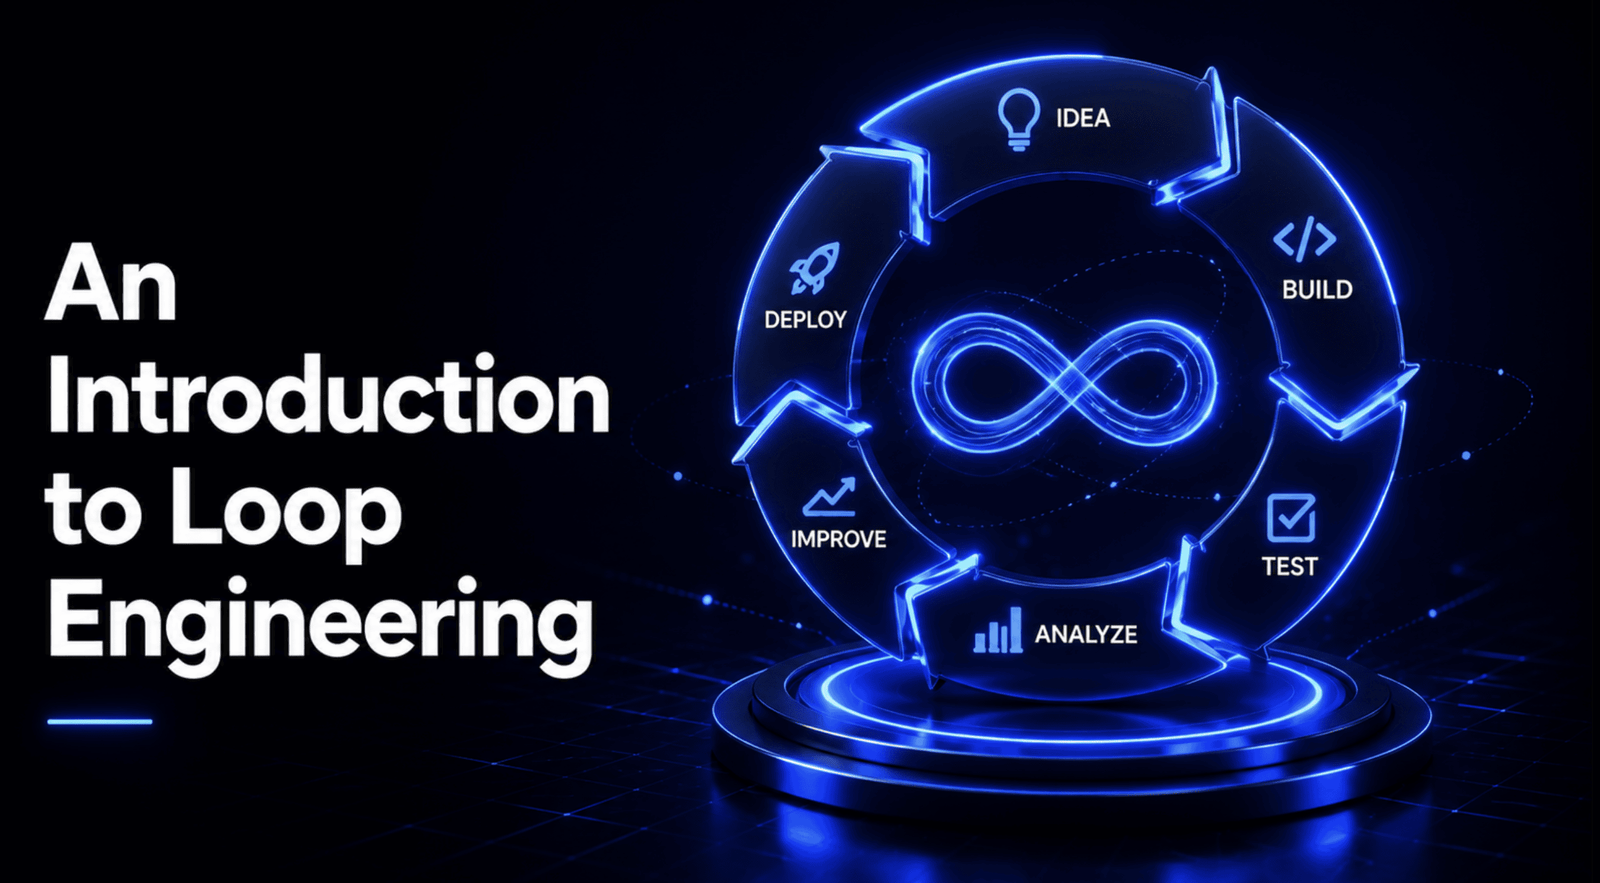
In this article, you will learn what loop engineering is, where it came from, and how to design autonomous AI agent cycles that run reliably without constant human supervision. Topics we will cover include: The origin and definition of loop engineering, and how it fits into the broader progression from prompt engineering to context engineering to harness engineering. The anatomy of a reliable loop, including its essential components, common patterns, and the pseudocode skeleton that underlies nearly every production implementation today. The three hardest problems in loop engineering — context management, termination, and verification — and the failure modes that result from getting any one of them wrong. Introduction A few months ago, a developer’s evening looked like this: open the coding agent, type an instruction, wait, read what came back, paste the error into the chat, wait again, nudge it in a slightly different direction, and repeat until the feature actually worked or until it was time to sleep. The agent was doing real work, but the human was still holding it the entire time, one turn after another, like driving a car that needs a hand on the wheel every three seconds. That evening looks different now for a growing number of engineers. They write one instruction, close the laptop, and come back the next morning to a draft pull request, a triaged issue list, or a green CI build, along with a readable trail of what the agent tried and why. Nobody stood over it, typing the next prompt. What changed wasn’t the model. It was what got built around the model. The name that stuck for that shift is loop engineering, and it went from a niche phrase to something people were debating on every timeline within about a week in June 2026. This article walks through where the term came from, the research it actually descends from, what a loop is made of, and how to build a small one of your own. What Loop Engineering Actually Means Loop engineering is the practice of designing the system that prompts, checks, remembers, and re-runs an AI agent, instead of a person doing all of that by hand, turn by turn. The unit of work stops being a single prompt or even a single conversation. It becomes a loop: a repeating cycle where the model takes an action, gets feedback from its environment, uses that feedback to decide what to do next, and keeps going until a real, checkable condition is met. It helps to hold this next to the thing it’s replacing. A chain runs in a fixed order: step A leads to step B, which leads to step C, and that’s it. A loop is dynamic. The agent might go from A to B, discover B didn’t work, revise its approach, and only then move to C, or it might loop back to A entirely. MindStudio’s breakdown of the concept puts it plainly: a loop continues until a task is genuinely complete, a stopping condition triggers, or the agent determines it can’t go any further. That’s a fundamentally different shape of work than “ask once, get an answer, copy it out.” The other framing worth sitting with is the “recursive goal” idea. Instead of typing each next step, you define a purpose — something like “make the test suite pass” or “triage every open issue and draft fixes for the straightforward ones” — and the agent iterates on its own toward that purpose: inspect the code, make a change, run a check, read the outcome, decide the next move. The skill shifts from writing one very good sentence to designing a cycle you trust enough to walk away from. How This Became a Term Almost Overnight It’s worth being specific about the timeline here, because the speed is part of the story. On June 7, 2026, developer Peter Steinberger, known for the OpenClaw agent project, posted on X that the relevant skill had already changed: you shouldn’t be prompting coding agents anymore, you should be designing the loops that prompt them for you. That post reportedly crossed 6.5 million views within days and dominated agent-focused conversation for the following week. The very next day, Google engineer and author Addy Osmani published an essay titled simply “Loop Engineering” that took Steinberger’s claim and gave it an actual anatomy: automations, worktrees, skills, connectors, and sub-agents, plus a sixth piece underneath all of it — external memory. That essay is what turned a viral take into a vocabulary that other people could build on and argue about. It wasn’t only outsiders making this case. Boris Cherny, who leads Claude Code at Anthropic, is quoted by Osmani as saying, “I don’t prompt Claude anymore. I have loops running that prompt Claude, and figuring out what to do. My job is to write loops.” When the person building one of the most-used coding agents on the market says he’s stopped prompting it directly, the idea has clearly moved past a fringe opinion. The timing makes sense once you look at what changed underneath it. By mid-2026, coding agents had gotten good enough to run unattended for genuinely long stretches, recovering from their own mistakes along the way, rather than needing correction every second or third step. Once a single agent run can last an hour and touch dozens of files, the bottleneck isn’t the sharpness of your prompt anymore. It’s whether you’ve built a cycle that keeps the agent productive, checked, and pointed at the right goal for the whole hour — including the part where nobody’s watching. Where It Fits: Prompt, Context, Harness, Loop Loop engineering didn’t appear out of nowhere, and it helps to see it as the newest layer in a steady progression outward, each one wrapping the previous layer rather than replacing it. Prompt engineering came first, roughly 2022 through 2024. The skill was wording: giving the model a role, breaking a task into steps, providing examples, and asking it to reason step by step.
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/russia-charges-telegram-founder-pavel-durov-with-facilitating-terrorism-issues-international-arrest-warrant-3063663.html” on this server. Reference #18.eff43717.1785482992.18ca4e28 https://errors.edgesuite.net/18.eff43717.1785482992.18ca4e28
5 Architectural Patterns for Persistent Memory and State in AI Agents
Memory & State For AI Agents Building an AI agent can be tricky. Keeping it on track over a six-month deployment is incredibly hard. LLMs are stateless by design. Every call starts from scratch, with no memory of what came before. Early agent developers worked around this by dumping the entire conversation history into the context window and hoping for the best. By now, we know that approach breaks down fast. Latency spikes, and the model’s ability to actually use what’s in context degrades: relevant facts get buried, and when two versions of a fact are both in the window, there’s no guarantee it picks the current one. Token costs balloon too, though prompt caching has softened that blow for stable prefixes. The fix isn’t a bigger context window; it’s treating memory and state as deliberate architectural decisions, not afterthoughts. Before getting into the patterns, it’s worth being precise about what those two terms mean, because they’re easy to conflate. State is a snapshot. It’s everything the agent currently knows about a task right now: what step it’s on, what the last tool call returned, what variables it’s tracking. Think of it as a whiteboard. It gets updated constantly as the task progresses, and when the session ends it’s gone, unless you deliberately persist it, which is what Pattern 2 is about. Memory is the mechanism that carries information across a boundary: the next turn, the next session, or a completely separate agent running later. Working memory is the shortest-horizon case (turn to turn); semantic and episodic memory span sessions. The two interact in a specific cycle. At the start of a task, the agent reads from memory to build its initial state: loading relevant facts, applicable behavioral rules, and records of past failures on similar tasks. During the task, the agent updates state continuously as it works. As the task progresses and concludes, it writes select pieces of that state back to memory so the next turn or session can benefit from what just happened. Memory feeds into state; state feeds back into memory. This distinction matters because the failure modes are different. A broken state means the agent loses track of what it’s doing mid-task. Broken memory means the agent can’t learn, can’t personalize, and treats every interaction like a blank slate. Both failures are common in production systems, and they require different fixes. The five patterns below address both: Patterns 1 and 2 manage state; 3 and 4 build the memory layer that persists across sessions; and 5 constrains both. 1. The In-Context Working Buffer (Short-Term Execution) The Concept Working memory holds the ephemeral state of the current session: the active prompt, recent conversational turns, and live tool outputs. Think of it as the agent’s short-term scratch space, flushed when the session ends. How It Works Rather than letting the message list grow indefinitely, the working buffer acts as a sliding window. The agent writes immediate reasoning steps to a scratchpad. As the buffer approaches a token limit, a summarization process compresses older turns into a dense background summary, keeping the logical conclusions and dropping the raw tool outputs. When the task wraps up, the buffer is flushed: anything worth keeping gets extracted to long-term stores, and the rest is discarded. Worth noting: that mid-conversation summarization may rewrite the prompt prefix, which invalidates the KV cache and creates a latency spike on the very next call. It’s a real tradeoff to design around. When To Use It Every agent needs this. It’s the baseline for handling multi-step reasoning within a session. 2. Execution Checkpointing (Fault Tolerance & Pausing) Once you have a strategy for managing what the agent holds in memory during a session, the next question is what happens when that session is interrupted. The Concept Long-running tasks fail. An agent might time out, hit a rate limit, or pause waiting for a human to approve an action. Checkpointing saves the agent’s workflow state to a database so execution can resume exactly where it stopped, without re-running work that already completed. How It Works Graph-based frameworks model workflows as nodes and edges. After each step, the framework persists the workflow state, including variables, history, and current position, to a durable store like PostgreSQL or SQLite. If the agent crashes, it reloads the last checkpoint and picks up from there. One thing practitioners regularly get burned by: resumption doesn’t give you exactly-once semantics. If a node partially executed before crashing (say it sent an email or wrote a database row), it may execute again on resume. Side-effecting nodes need to be idempotent. Also keep in mind that open file handles and client objects can’t be checkpointed, which limits what you can safely put in state. When To Use It Essential for human-in-the-loop systems, regulated workflows where actions need approval, and any long-horizon task susceptible to network failures. 3. Semantic Memory (Cross-Session Knowledge) Checkpointing handles continuity within a task. But what about knowledge that needs to survive across entirely separate sessions? The Concept Semantic memory is what the agent knows: facts, user preferences, and domain knowledge that persist across independent sessions. How It Works Facts are extracted asynchronously and stored in an external database, usually a vector store with metadata filtering, sometimes paired with a knowledge graph where relationship traversal genuinely matters. When a query comes in, the system retrieves the most relevant facts and injects them into the prompt before the model sees it. Note that extraction may cost an additional LLM call or more, depending on architecture, and often one per turn. One conflict to design around: if a user mentions “I use Postgres” in March and “we migrated to Snowflake” in July, both facts end up in the store. Retrieval might surface either one. Fact invalidation, through recency weighting, supersession logic, or TTLs, is what actually solves the stale fact problem raised at the top. Also worth calling out explicitly: credentials and secrets are not semantic memory. Don’t store API keys in a retrievable