
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/world-quantum-day-2026-why-is-it-celebrated-history-significance-purpose-all-you-need-to-know-3037141.html” on this server. Reference #18.c4f43717.1776167909.b0f5cd28 https://errors.edgesuite.net/18.c4f43717.1776167909.b0f5cd28
Handling Race Conditions in Multi-Agent Orchestration
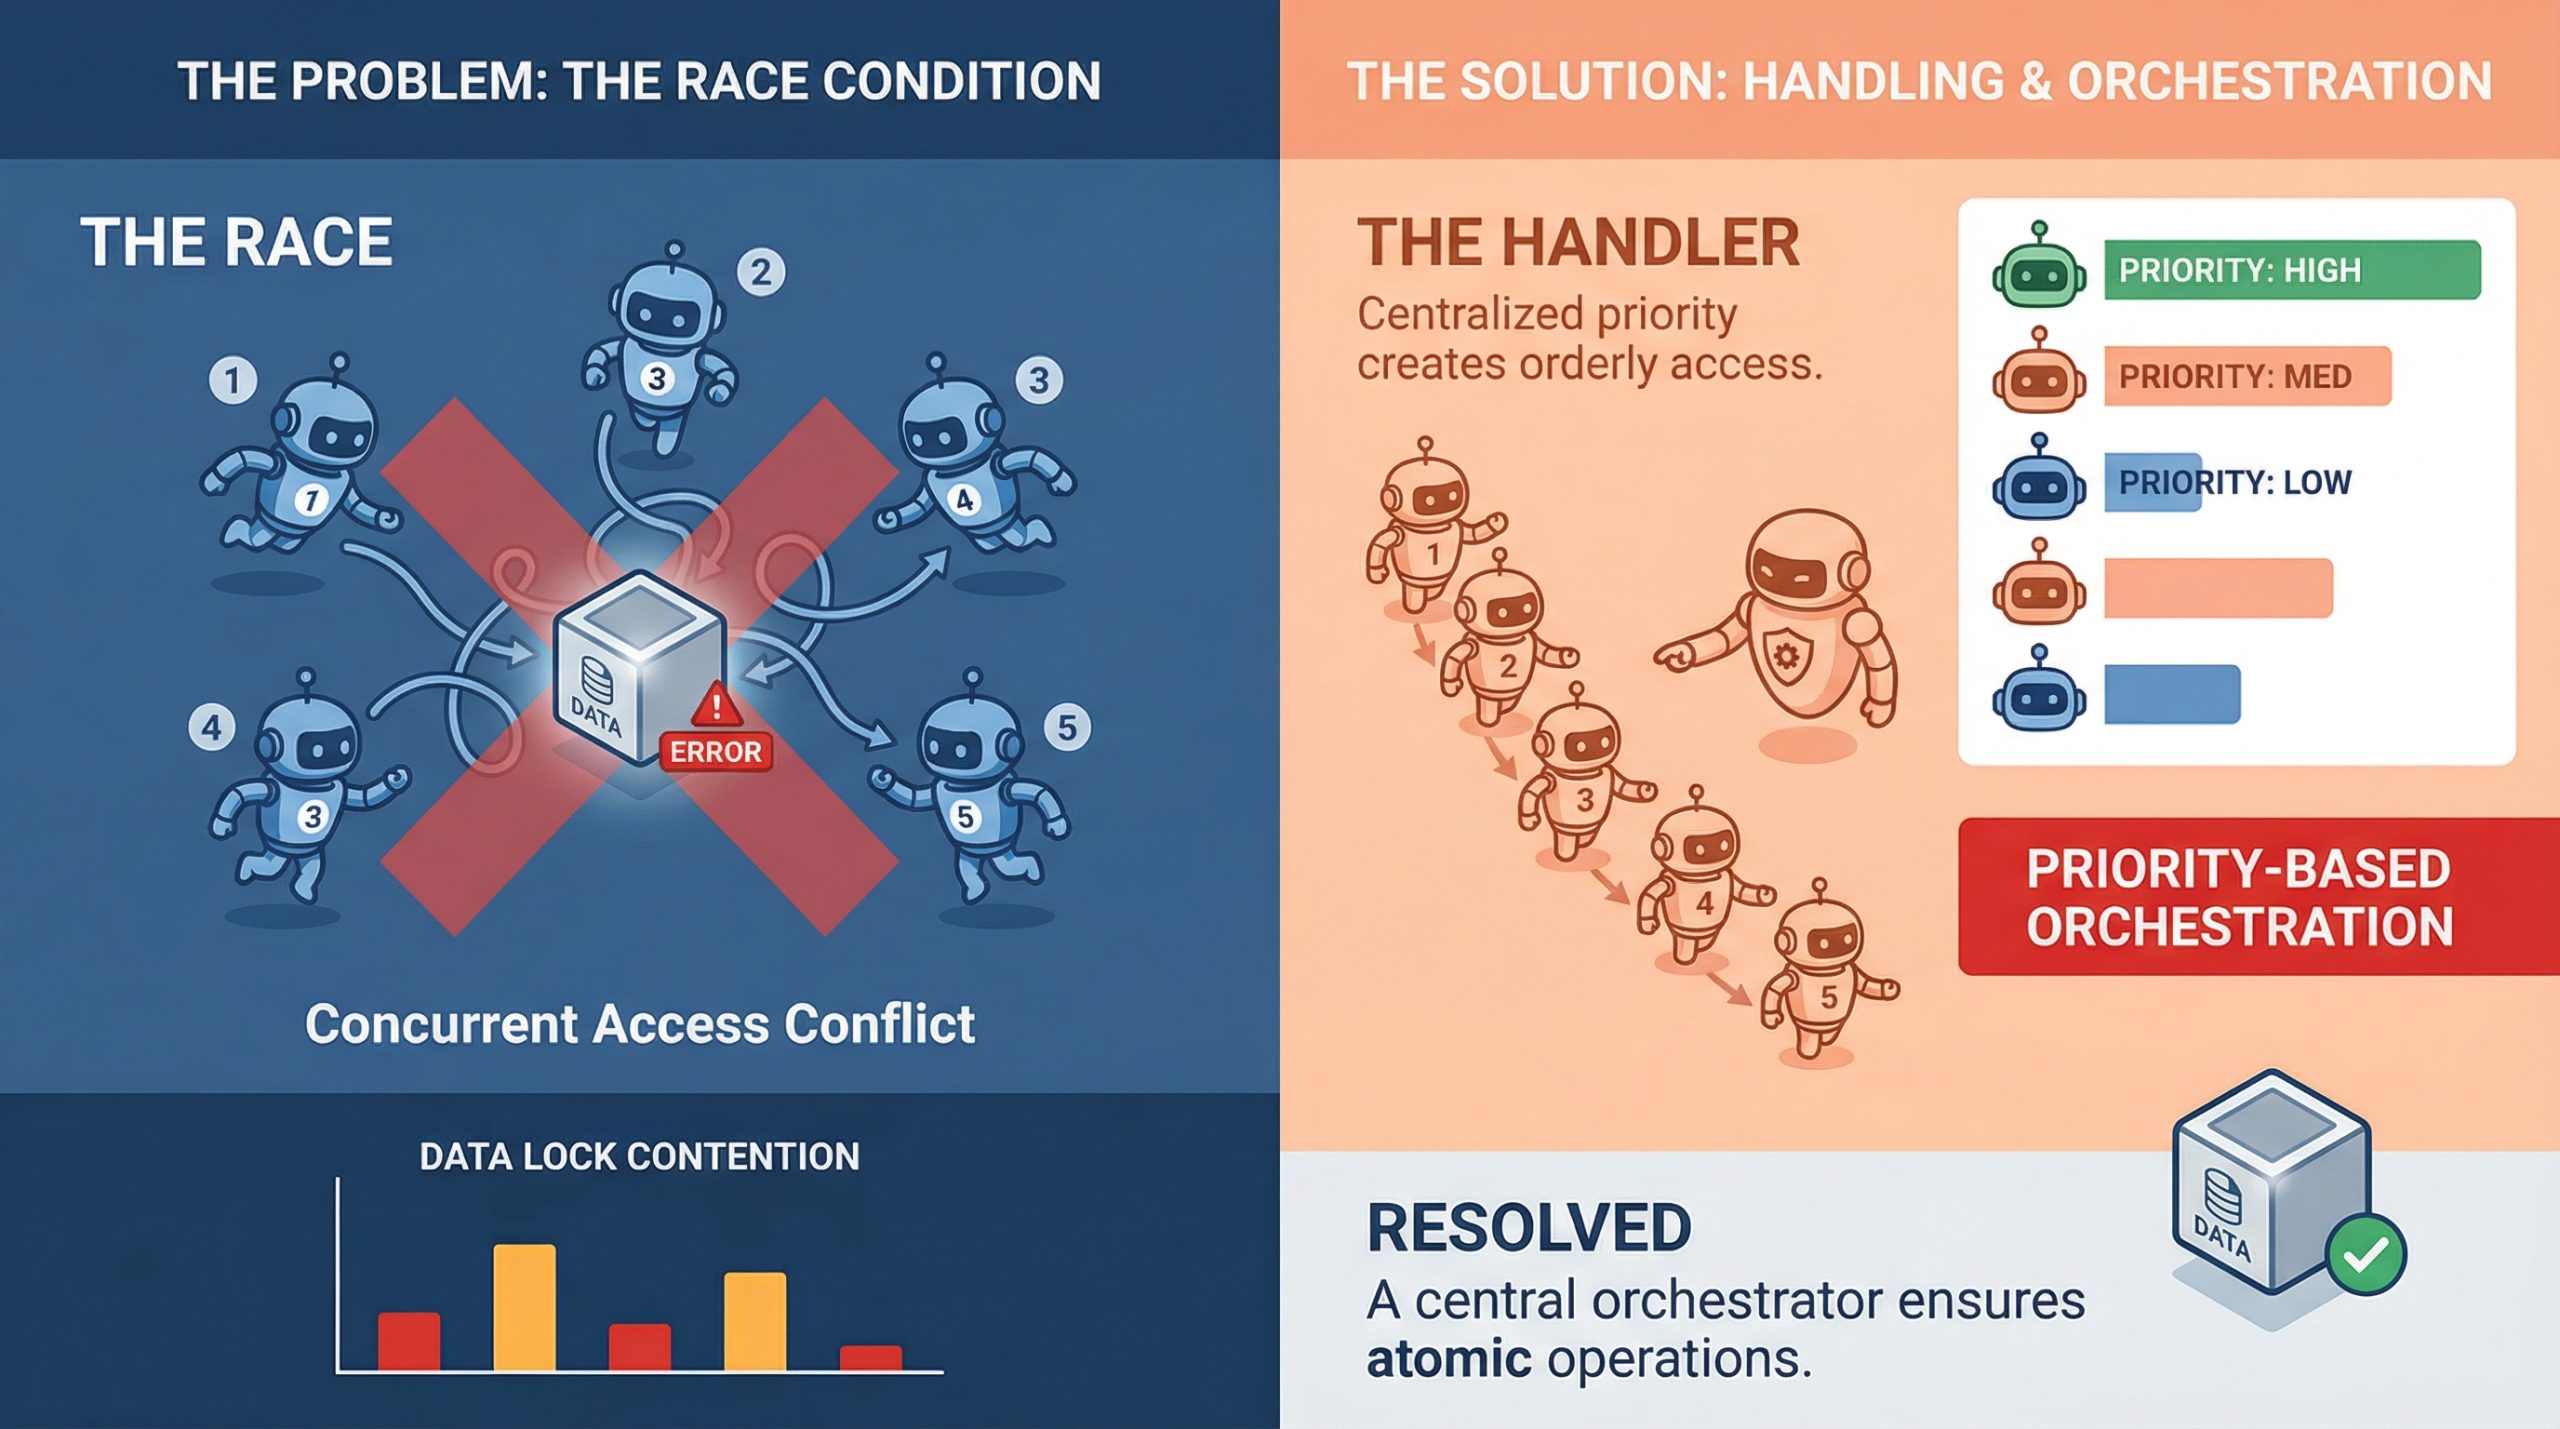
In this article, you will learn how to identify, understand, and mitigate race conditions in multi-agent orchestration systems. Topics we will cover include: What race conditions look like in multi-agent environments Architectural patterns for preventing shared-state conflicts Practical strategies like idempotency, locking, and concurrency testing Let’s get straight to it. Handling Race Conditions in Multi-Agent OrchestrationImage by Editor If you’ve ever watched two agents confidently write to the same resource at the same time and produce something that makes zero sense, you already know what a race condition feels like in practice. It’s one of those bugs that doesn’t show up in unit tests, behaves perfectly in staging, and then detonates in production during your highest-traffic window. In multi-agent systems, where parallel execution is the whole point, race conditions aren’t edge cases. They’re expected guests. Understanding how to handle them is less about being defensive and more about building systems that assume chaos by default. What Race Conditions Actually Look Like in Multi-Agent Systems A race condition happens when two or more agents try to read, modify, or write shared state at the same time, and the final result depends on which one gets there first. In a single-agent pipeline, that’s manageable. In a system with five agents running concurrently, it’s a genuinely different problem. The tricky part is that race conditions aren’t always obvious crashes. Sometimes they’re silent. Agent A reads a document, Agent B updates it half a second later, and Agent A writes back a stale version with no error thrown anywhere. The system looks fine. The data is compromised. What makes this worse in machine learning pipelines specifically is that agents often work on mutable shared objects, whether that’s a shared memory store, a vector database, a tool output cache, or a simple task queue. Any of these can become a contention point when multiple agents start pulling from them simultaneously. Why Multi-Agent Pipelines Are Especially Vulnerable Traditional concurrent programming has decades of tooling around race conditions: threads, mutexes, semaphores, and atomic operations. Multi-agent large language model (LLM) systems are newer, and they are often built on top of async frameworks, message brokers, and orchestration layers that don’t always give you fine-grained control over execution order. There’s also the problem of non-determinism. LLM agents don’t always take the same amount of time to complete a task. One agent might finish in 200ms, while another takes 2 seconds, and the orchestrator has to handle that gracefully. When it doesn’t, agents start stepping on each other, and you end up with a corrupted state or conflicting writes that the system silently accepts. Agent communication patterns matter a lot here, too. If agents are sharing state through a central object or a shared database row rather than passing messages, they are almost guaranteed to run into write conflicts at scale. This is as much a design pattern issue as it is a concurrency issue, and fixing it usually starts at the architecture level before you even touch the code. Locking, Queuing, and Event-Driven Design The most direct way to handle shared resource contention is through locking. Optimistic locking works well when conflicts are rare: each agent reads a version tag alongside the data, and if the version has changed by the time it tries to write, the write fails and retries. Pessimistic locking is more aggressive and reserves the resource before reading. Both approaches have trade-offs, and which one fits depends on how often your agents are actually colliding. Queuing is another solid approach, especially for task assignment. Instead of multiple agents polling a shared task list directly, you push tasks into a queue and let agents consume them one at a time. Systems like Redis Streams, RabbitMQ, or even a basic Postgres advisory lock can handle this well. The queue becomes your serialization point, which takes the race out of the equation for that particular access pattern. Event-driven architectures go further. Rather than agents reading from shared state, they react to events. Agent A completes its work and emits an event. Agent B listens for that event and picks up from there. This creates looser coupling and naturally reduces the overlap window where two agents might be modifying the same thing at once. Idempotency Is Your Best Friend Even with solid locking and queuing in place, things still go wrong. Networks hiccup, timeouts happen, and agents retry failed operations. If those retries are not idempotent, you will end up with duplicate writes, double-processed tasks, or compounding errors that are painful to debug after the fact. Idempotency means that running the same operation multiple times produces the same result as running it once. For agents, that often means including a unique operation ID with every write. If the operation has already been applied, the system recognizes the ID and skips the duplicate. It’s a small design choice with a significant impact on reliability. It’s worth building idempotency in from the start at the agent level. Retrofitting it later is painful. Agents that write to databases, update records, or trigger downstream workflows should all carry some form of deduplication logic, because it makes the whole system more resilient to the messiness of real-world execution. Testing for Race Conditions Before They Test You The hard part about race conditions is reproducing them. They are timing-dependent, which means they often only appear under load or in specific execution sequences that are difficult to reproduce in a controlled test environment. One useful approach is stress testing with intentional concurrency. Spin up multiple agents against a shared resource simultaneously and observe what breaks. Tools like Locust, pytest-asyncio with concurrent tasks, or even a simple ThreadPoolExecutor can help simulate the kind of overlapping execution that exposes contention bugs in staging rather than production. Property-based testing is underused in this context. If you can define invariants that should always hold regardless of execution order, you can run randomized tests that attempt to violate them. It won’t catch everything, but it will surface many of the
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/how-to-solve-smartphone-lagging-problems-here-are-5-simple-tips-to-fix-it-3035998.html” on this server. Reference #18.eff43717.1776122794.83144fe2 https://errors.edgesuite.net/18.eff43717.1776122794.83144fe2
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/infinix-note-60-pro-launched-in-india-price-features-camera-battery-and-all-you-need-to-know-3036994.html” on this server. Reference #18.c4f43717.1776090862.a4a25aa2 https://errors.edgesuite.net/18.c4f43717.1776090862.a4a25aa2
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/whatsapp-for-carplay-launched-key-features-and-uses-how-it-benefits-drivers-and-passengers-3036253.html” on this server. Reference #18.c4f43717.1776062548.9f944c18 https://errors.edgesuite.net/18.c4f43717.1776062548.9f944c18
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/samsung-to-discontinue-samsung-messages-app-in-july-2026-urges-switch-to-google-messages-3036504.html” on this server. Reference #18.c4f43717.1776004228.970d1bf2 https://errors.edgesuite.net/18.c4f43717.1776004228.970d1bf2
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/what-is-the-length-of-your-smartphone-charging-cable-iphone-vs-android-is-there-a-difference-3036294.html” on this server. Reference #18.c4f43717.1775983887.91f69cfc https://errors.edgesuite.net/18.c4f43717.1775983887.91f69cfc
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/google-ai-features-you-can-now-book-restaurant-tables-from-search-bar-check-how-it-works-3036021.html” on this server. Reference #18.c4f43717.1775917569.87795687 https://errors.edgesuite.net/18.c4f43717.1775917569.87795687
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/ai-race-heats-up-anthropic-may-build-its-own-chips-to-power-claude-ai-key-reasons-behind-this-move-3035782.html” on this server. Reference #18.c4f43717.1775880506.7fa9a0d4 https://errors.edgesuite.net/18.c4f43717.1775880506.7fa9a0d4
A Hands-On Guide to Testing Agents with RAGAs and G-Eval
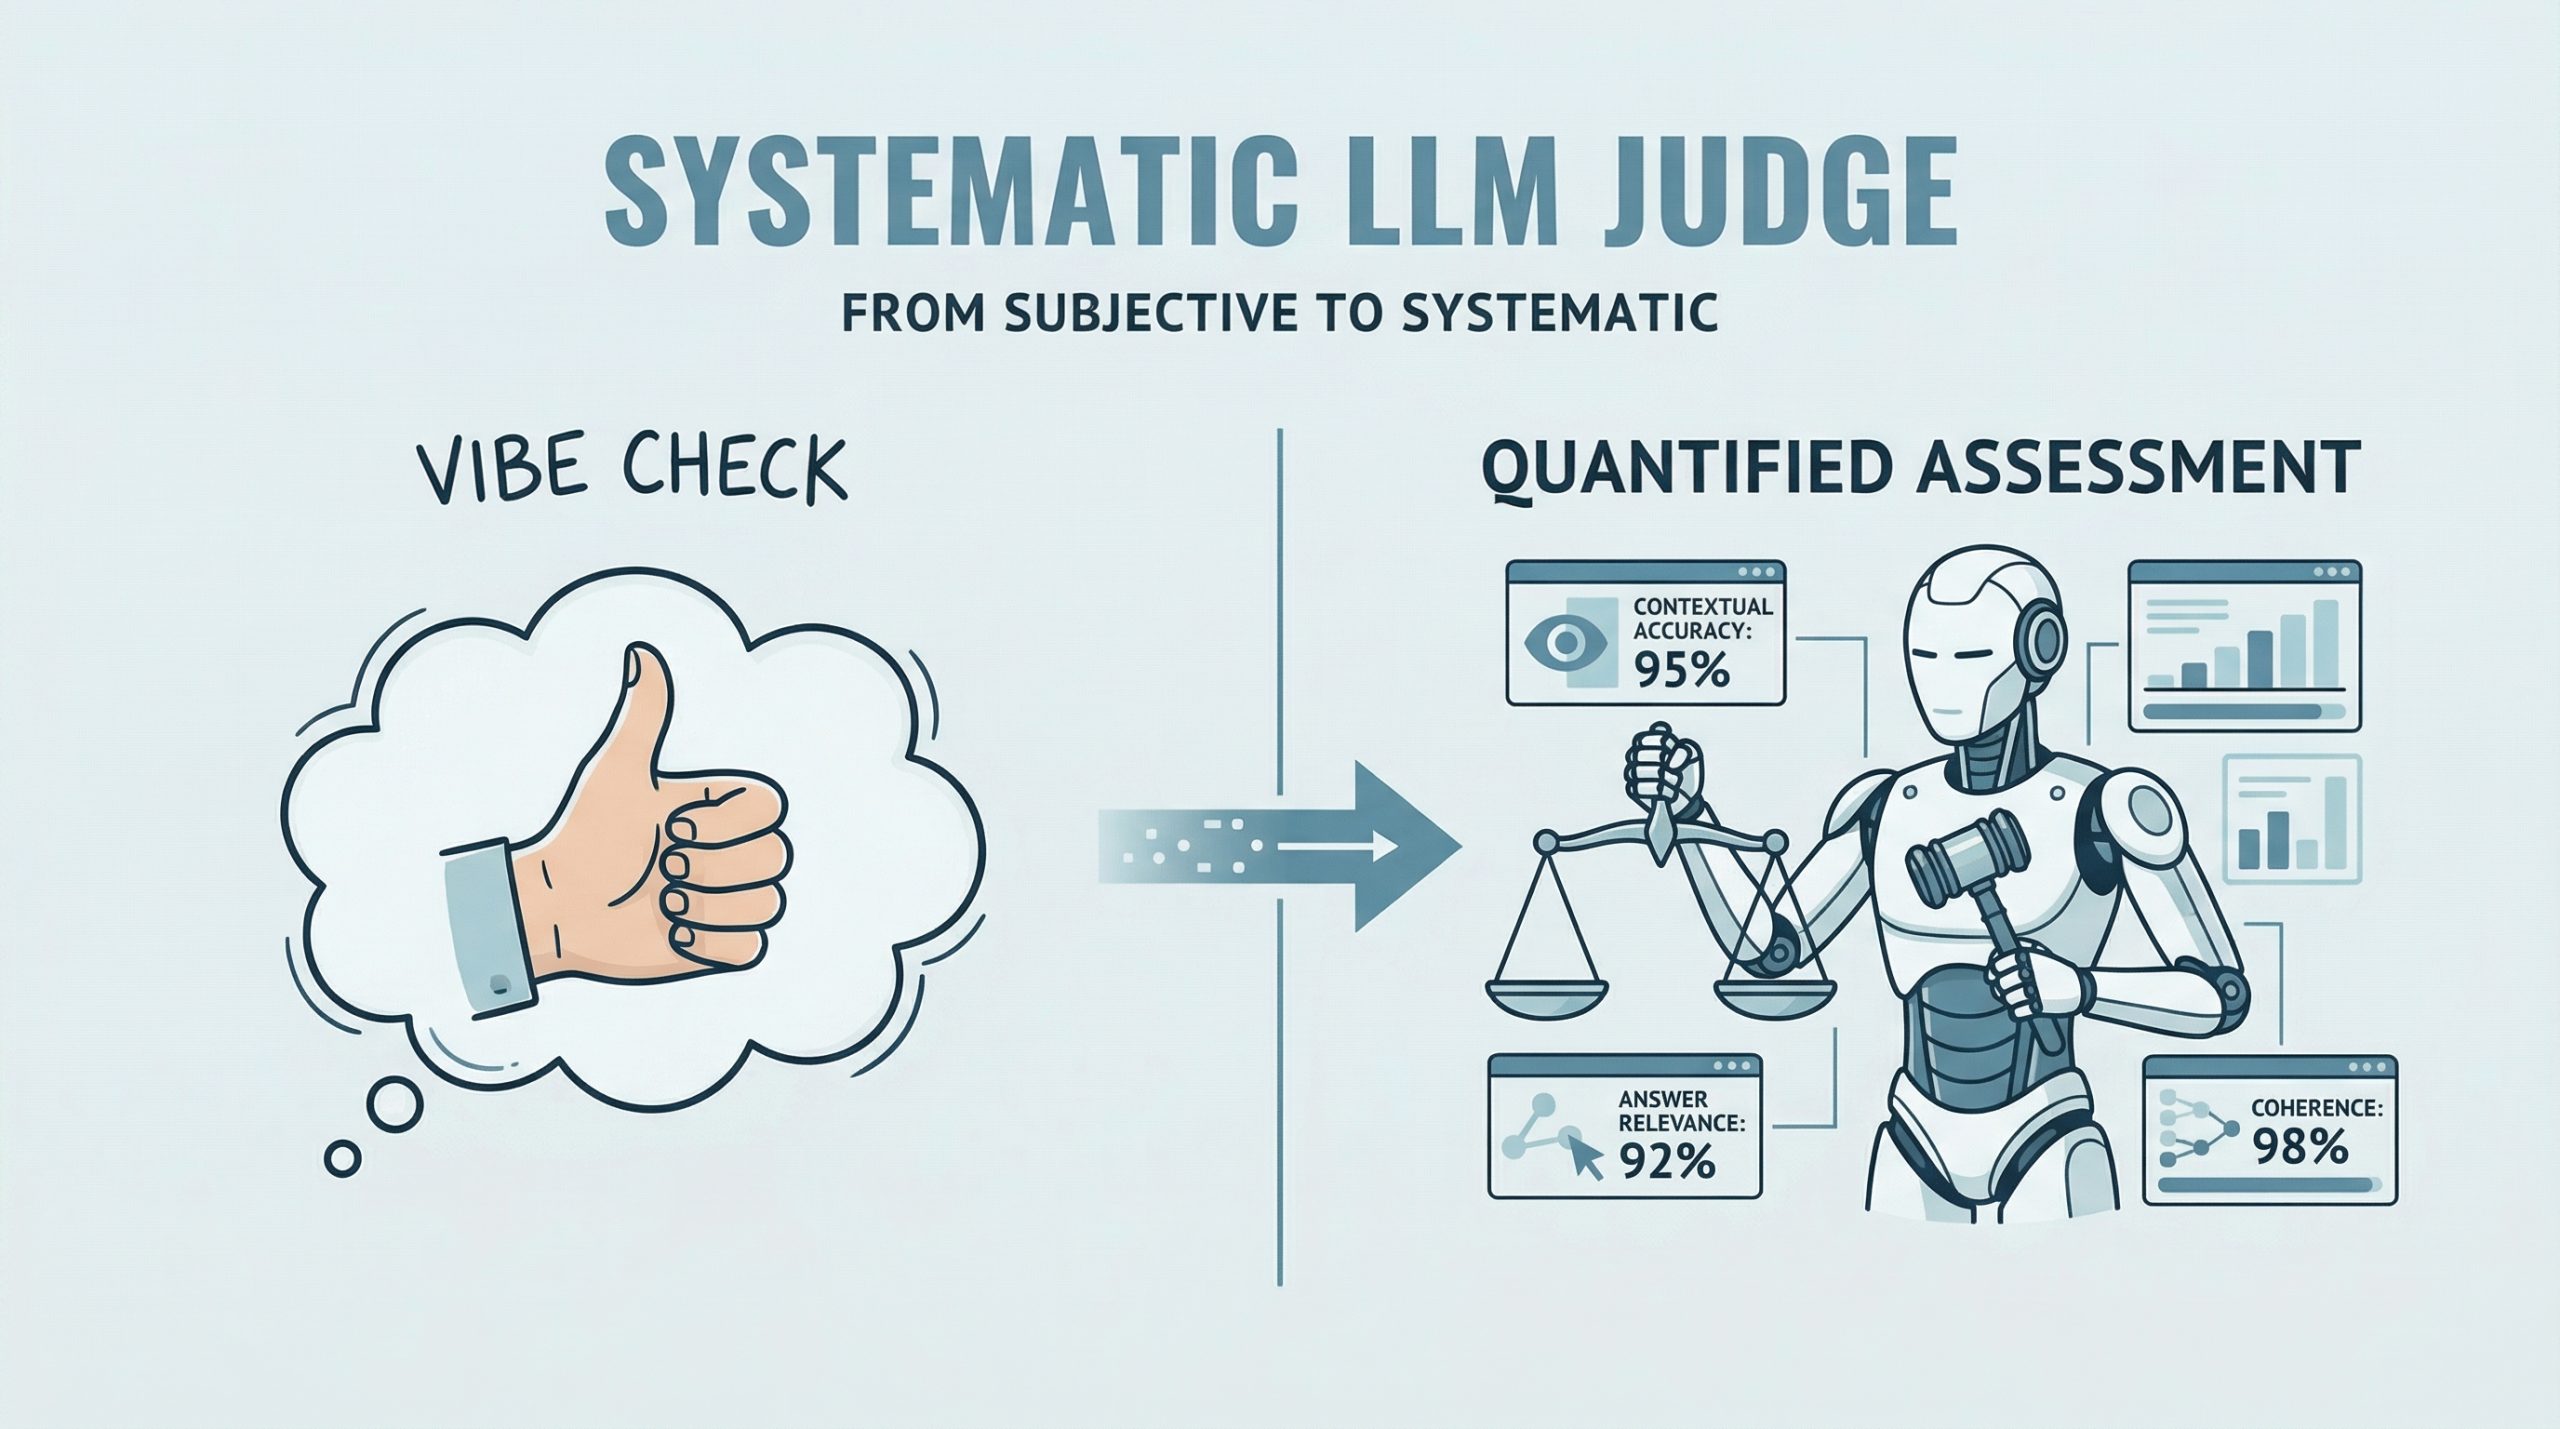
In this article, you will learn how to evaluate large language model applications using RAGAs and G-Eval-based frameworks in a practical, hands-on workflow. Topics we will cover include: How to use RAGAs to measure faithfulness and answer relevancy in retrieval-augmented systems. How to structure evaluation datasets and integrate them into a testing pipeline. How to apply G-Eval via DeepEval to assess qualitative aspects like coherence. Let’s get started. A Hands-On Guide to Testing Agents with RAGAs and G-EvalImage by Editor Introduction RAGAs (Retrieval-Augmented Generation Assessment) is an open-source evaluation framework that replaces subjective “vibe checks” with a systematic, LLM-driven “judge” to quantify the quality of RAG pipelines. It assesses a triad of desirable RAG properties, including contextual accuracy and answer relevance. RAGAs has also evolved to support not only RAG architectures but also agent-based applications, where methodologies like G-Eval play a role in defining custom, interpretable evaluation criteria. This article presents a hands-on guide to understanding how to test large language model and agent-based applications using both RAGAs and frameworks based on G-Eval. Concretely, we will leverage DeepEval, which integrates multiple evaluation metrics into a unified testing sandbox. If you are unfamiliar with evaluation frameworks like RAGAs, consider reviewing this related article first. Step-by-Step Guide This example is designed to work both in a standalone Python IDE and in a Google Colab notebook. You may need to pip install some libraries along the way to resolve potential ModuleNotFoundError issues, which occur when attempting to import modules that are not installed in your environment. We begin by defining a function that takes a user query as input and interacts with an LLM API (such as OpenAI) to generate a response. This is a simplified agent that encapsulates a basic input-response workflow. import openai def simple_agent(query): # NOTE: this is a ‘mock’ agent loop # In a real scenario, you would use a system prompt to define tool usage prompt = f”You are a helpful assistant. Answer the user query: {query}” # Example using OpenAI (this can be swapped for Gemini or another provider) response = openai.chat.completions.create( model=”gpt-3.5-turbo”, messages=[{“role”: “user”, “content”: prompt}] ) return response.choices[0].message.content import openai def simple_agent(query): # NOTE: this is a ‘mock’ agent loop # In a real scenario, you would use a system prompt to define tool usage prompt = f“You are a helpful assistant. Answer the user query: {query}” # Example using OpenAI (this can be swapped for Gemini or another provider) response = openai.chat.completions.create( model=“gpt-3.5-turbo”, messages=[{“role”: “user”, “content”: prompt}] ) return response.choices[0].message.content In a more realistic production setting, the agent defined above would include additional capabilities such as reasoning, planning, and tool execution. However, since the focus here is on evaluation, we intentionally keep the implementation simple. Next, we introduce RAGAs. The following code demonstrates how to evaluate a question-answering scenario using the faithfulness metric, which measures how well the generated answer aligns with the provided context. from ragas import evaluate from ragas.metrics import faithfulness # Defining a simple testing dataset for a question-answering scenario data = { “question”: [“What is the capital of Japan?”], “answer”: [“Tokyo is the capital.”], “contexts”: [[“Japan is a country in Asia. Its capital is Tokyo.”]] } # Running RAGAs evaluation result = evaluate(data, metrics=[faithfulness]) from ragas import evaluate from ragas.metrics import faithfulness # Defining a simple testing dataset for a question-answering scenario data = { “question”: [“What is the capital of Japan?”], “answer”: [“Tokyo is the capital.”], “contexts”: [[“Japan is a country in Asia. Its capital is Tokyo.”]] } # Running RAGAs evaluation result = evaluate(data, metrics=[faithfulness]) Note that you may need sufficient API quota (e.g., OpenAI or Gemini) to run these examples, which typically requires a paid account. Below is a more elaborate example that incorporates an additional metric for answer relevancy and uses a structured dataset. test_cases = [ { “question”: “How do I reset my password?”, “answer”: “Go to settings and click ‘forgot password’. An email will be sent.”, “contexts”: [“Users can reset passwords via the Settings > Security menu.”], “ground_truth”: “Navigate to Settings, then Security, and select Forgot Password.” } ] test_cases = [ { “question”: “How do I reset my password?”, “answer”: “Go to settings and click ‘forgot password’. An email will be sent.”, “contexts”: [“Users can reset passwords via the Settings > Security menu.”], “ground_truth”: “Navigate to Settings, then Security, and select Forgot Password.” } ] Ensure that your API key is configured before proceeding. First, we demonstrate evaluation without wrapping the logic in an agent: import os from ragas import evaluate from ragas.metrics import faithfulness, answer_relevancy from datasets import Dataset # IMPORTANT: Replace “YOUR_API_KEY” with your actual API key os.environ[“OPENAI_API_KEY”] = “YOUR_API_KEY” # Convert list to Hugging Face Dataset (required by RAGAs) dataset = Dataset.from_list(test_cases) # Run evaluation ragas_results = evaluate(dataset, metrics=[faithfulness, answer_relevancy]) print(f”RAGAs Faithfulness Score: {ragas_results[‘faithfulness’]}”) import os from ragas import evaluate from ragas.metrics import faithfulness, answer_relevancy from datasets import Dataset # IMPORTANT: Replace “YOUR_API_KEY” with your actual API key os.environ[“OPENAI_API_KEY”] = “YOUR_API_KEY” # Convert list to Hugging Face Dataset (required by RAGAs) dataset = Dataset.from_list(test_cases) # Run evaluation ragas_results = evaluate(dataset, metrics=[faithfulness, answer_relevancy]) print(f“RAGAs Faithfulness Score: {ragas_results[‘faithfulness’]}”) To simulate an agent-based workflow, we can encapsulate the evaluation logic into a reusable function: import os from ragas import evaluate from ragas.metrics import faithfulness, answer_relevancy from datasets import Dataset def evaluate_ragas_agent(test_cases, openai_api_key=”YOUR_API_KEY”): “””Simulates a simple AI agent that performs RAGAs evaluation.””” os.environ[“OPENAI_API_KEY”] = openai_api_key # Convert test cases into a Dataset object dataset = Dataset.from_list(test_cases) # Run evaluation ragas_results = evaluate(dataset, metrics=[faithfulness, answer_relevancy]) return ragas_results 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 import os from ragas import evaluate from ragas.metrics import faithfulness, answer_relevancy from datasets import Dataset def evaluate_ragas_agent(test_cases, openai_api_key=“YOUR_API_KEY”): “”“Simulates a simple AI agent that performs RAGAs evaluation.”“” os.environ[“OPENAI_API_KEY”] = openai_api_key # Convert test cases into a Dataset object dataset = Dataset.from_list(test_cases) # Run evaluation ragas_results = evaluate(dataset,

