
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/whatsapp-username-feature-no-need-to-share-phone-numbers-now-heres-how-to-create-and-reserve-your-username-3058639.html” on this server. Reference #18.eff43717.1782881389.133d2dee https://errors.edgesuite.net/18.eff43717.1782881389.133d2dee
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/oneplus-n6-launched-in-india-with-massive-8000mah-battery-price-camera-and-specs-inside-3058500.html” on this server. Reference #18.c4f43717.1782809198.15f68dec https://errors.edgesuite.net/18.c4f43717.1782809198.15f68dec
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/amazon-prime-day-sale-samsung-galaxy-s25-ultra-now-available-for-under-rs-90000-check-offers-and-all-3058491.html” on this server. Reference #18.eff43717.1782804651.ef719c8 https://errors.edgesuite.net/18.eff43717.1782804651.ef719c8
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/meet-japans-new-ai-police-chief-aiko-how-shes-fighting-investment-and-romance-scams-3058478.html” on this server. Reference #18.c4f43717.1782795242.13d47283 https://errors.edgesuite.net/18.c4f43717.1782795242.13d47283
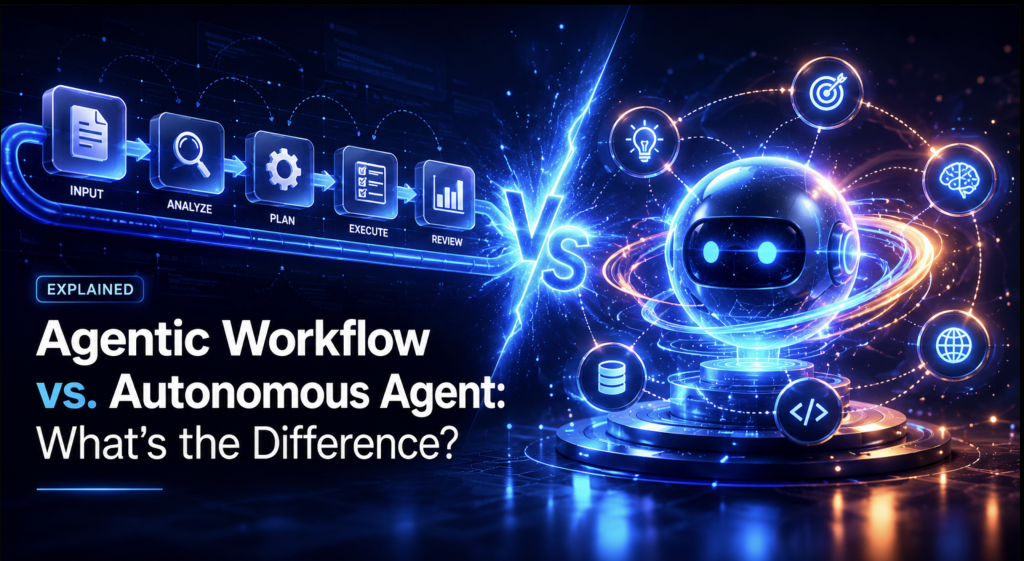
Agentic Workflow vs. Autonomous Agent: What’s the Difference?
In this article, you will learn how to distinguish agentic workflows from autonomous agents by focusing on who owns control flow — a human writing code in advance, or a model reasoning at runtime. Topics we will cover include: Why the real axis separating these systems is predictability versus autonomy, not whether an LLM is involved. How deterministic workflows, orchestrated workflows, reactive agents, and autonomous multi-agent systems differ, with runnable code that makes the control-flow distinction concrete. Why workflows, not fully autonomous agents, dominate production today, and why hybrid architectures are the pattern that holds up. Introduction Deloitte projects that by 2027, up to 50% of companies using generative AI will have launched agentic AI pilots or proofs of concept. That’s a wave of adoption big enough that the word “agentic” has started covering almost anything with an LLM call in it, from a fixed five-step pipeline where step three happens to call GPT for a summary to a fully self-directing system that plans its own path with no script at all. Those are not the same thing. Treating them as interchangeable leads to one of two mistakes: over-engineering a simple, well-understood task with unnecessary autonomy, or under-engineering a genuinely open-ended problem by forcing it into a rigid pipeline that breaks the moment reality deviates from the plan. Anthropic draws the foundational line in their widely cited “Building Effective Agents” piece: workflows are systems where LLMs and tools are orchestrated through predefined code paths. Agents are systems where LLMs dynamically direct their own process and tool usage, maintaining control over how they accomplish a task. Everything in this article is detailed underneath that one distinction. This piece maps the full spectrum of deterministic workflows, orchestrated systems, reactive single agents, and autonomous multi-agent systems, with code at each stage that makes the control-flow difference concrete rather than abstract. The code here illustrates architecture, not a deployable system; the point of each snippet is to show who decides what happens next, not to ship a feature. The Real Axis Isn’t “AI vs. No AI”: It’s Predictability vs. Autonomy Before comparing architectures, it’s worth replacing the wrong question. The question isn’t “does this system use an LLM.” Almost everything does now. The two questions that actually matter, borrowing a framing that’s gained real traction in architecture circles, are: does this process need to be repeatable, auditable, and explainable step-by-step? And: is the correct path even known in advance, or does the system need to discover it at runtime? A system can lean heavily on an LLM and still be fully deterministic in structure — a fixed pipeline where one step happens to call a model for text generation, but the next step is hardcoded regardless of what comes back. A system can also be “agentic” with very little real autonomy: a tightly scripted loop with only two allowed actions and a hard step limit. The presence of an LLM call is not the signal. Ownership of control flow is. Google Cloud’s own design-pattern documentation draws this exact line operationally: deterministic workflows include tasks with a clearly defined path known in advance, where the steps don’t change much from one run to the next. Workflows that require dynamic orchestration involve problems where the agent must determine the best way to proceed, without a predefined script. That’s the spectrum this article walks through, one stage at a time. Deterministic Workflows This is the baseline. A deterministic workflow has a known sequence of steps decided at design time, by a human, in code. An LLM can sit inside any step — generating text, classifying input, drafting a summary — but it does not choose what happens after its own step runs. The orchestrating code does that, regardless of what the model returns. # deterministic_pipeline.py # Prerequisites: none beyond Python’s standard library # Run: python deterministic_pipeline.py def mock_llm_classify(text: str) -> str: “”” Mock LLM call — stands in for a real API call to keep this example runnable without an API key. The point is structural: whatever this returns, the NEXT function that runs is already decided below. “”” if “refund” in text.lower() or “charge” in text.lower(): return “billing” return “general” def extract(raw_input: str) -> str: “””Step 1 — always runs, always leads to step 2. No branching here.””” return raw_input.strip() def classify(cleaned_text: str) -> str: “”” Step 2 — calls an LLM to produce a label, but the label has no effect on which function runs next. That’s the deterministic part: the model fills in a piece of data, it doesn’t influence the route. “”” label = mock_llm_classify(cleaned_text) print(f” [classify] LLM returned label=”{label}” (informational only)”) return cleaned_text def summarize(cleaned_text: str) -> str: “””Step 3 — always runs after step 2, regardless of the label from step 2.””” return f”Summary: {cleaned_text[:40]}…” def notify(summary: str) -> str: “””Step 4 — always runs last. The path is fixed at design time.””” return f”Notification sent: {summary}” def run_deterministic_pipeline(raw_input: str) -> str: “”” The control flow here is written entirely by a human, in advance. Every run takes the identical path: extract -> classify -> summarize -> notify. The LLM call inside classify() produces a label, but that label is never used to decide what function runs next — it’s data flowing through a fixed pipe. “”” step1 = extract(raw_input) step2 = classify(step1) step3 = summarize(step2) step4 = notify(step3) return step4 if __name__ == “__main__”: # Two inputs that the LLM would classify completely differently result_1 = run_deterministic_pipeline(“I want a refund for my last charge”) result_2 = run_deterministic_pipeline(“What are your business hours?”) print(f”\nResult 1: {result_1}”) print(f”Result 2: {result_2}”) 1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 # deterministic_pipeline.py # Prerequisites: none beyond
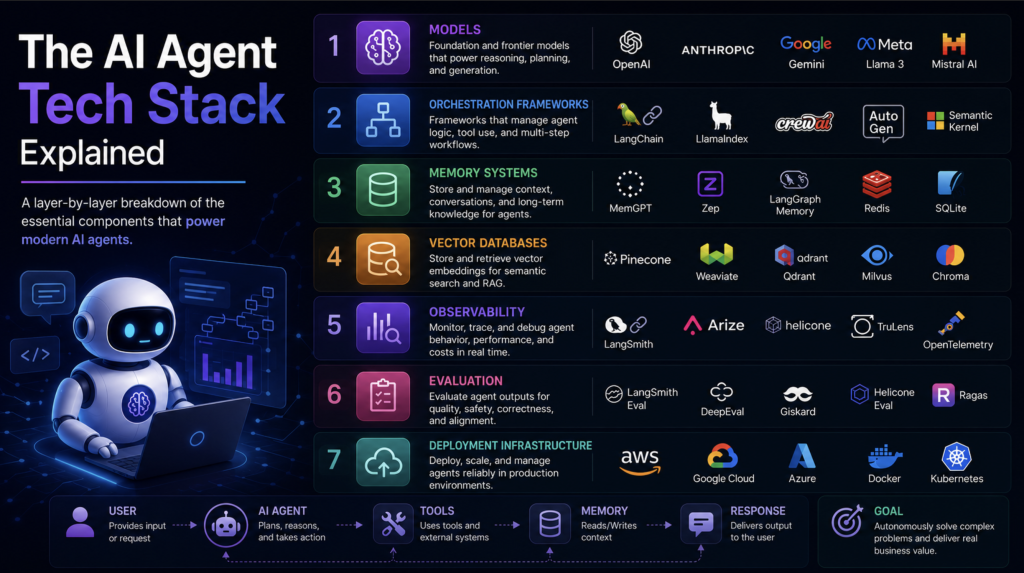
The AI Agent Tech Stack Explained
In this article, you will learn how the seven layers of a production AI agent stack fit together, from the foundation model down to deployment infrastructure. Topics we will cover include: What each layer of the stack does, from the foundation model and orchestration framework through memory, retrieval, tools, observability, and deployment. How to implement each layer with working code, including a stateful agent, a memory system, a RAG pipeline, custom tools, and tracing. Which combination of technologies to use at each layer depending on whether you are prototyping, scaling a startup, or operating in an enterprise environment. Introduction Picture this: you ask an AI agent to research three competitors, pull the pricing data from each of their websites, summarize the findings into a structured report, and drop it in a Slack channel by 9am. You hit enter. Thirty seconds later, the report is there. What just happened under the hood is not magic, and it is not one thing. It is seven distinct layers of technology working in sequence, each one handling a specific job, each one capable of breaking in its own specific way. The model at the top gets all the attention. The six layers beneath it are what determine whether the agent actually works. According to Gartner, 40% of enterprise applications will be integrated with task-specific AI agents by the end of 2026, up from less than 5% in 2025. That is not a gradual curve. That is a near-vertical adoption line, and the engineers and technical leads responsible for those deployments need to understand the full stack, not just the layer they happen to own. This article goes through each layer in order, from the foundation model down to deployment infrastructure. By the end, you will know what every piece is, why it exists, how the layers connect to each other, and what to actually use at each level. Layer 1: The Foundation Model The foundation model is the cognitive core of an agent. It is where reasoning happens, language is understood, and decisions about what to do next are made. Everything else in the stack is either feeding context into it or acting on what it produces. In practical terms, your main options in 2026 are OpenAI’s GPT-5.5, Anthropic’s Claude Sonnet 4.6 (or Claude Opus 4.8 for harder reasoning), Google’s Gemini 3.1 Pro, and open-weight models like Meta’s Llama 4 and Mistral Large 3. Each has trade-offs worth understanding before you commit. GPT-5.5 is fast for everyday calls and reliable at tool-calling, and it has the most mature ecosystem of integrations and the widest community of developers who have already run into and solved the edge cases you will encounter. Claude Sonnet 4.6 handles long documents and nuanced instruction-following well at a lower price point than Anthropic’s Opus tier, which matters in document-heavy workflows; reach for Claude Opus 4.8 when a task needs deeper, longer-horizon reasoning. Gemini 3.1 Pro has a 1 million token context window, which is relevant if your agent needs to process large codebases or lengthy knowledge bases in a single pass. Open-weight models like Llama 4 give you full control over deployment and data residency, at the cost of the infrastructure overhead of running them yourself. There is no longer a hard split between “standard” and “reasoning” model families, the way there was in 2025; OpenAI, Anthropic, and Google have each folded reasoning into a single model that decides how long to think. GPT-5.5 ships with adjustable reasoning effort levels (from none up to xhigh), and the same applies to Claude’s effort parameter and Gemini’s thinking levels. For most agent workflows, the default or low-effort setting is the right choice: fast and cheap. For tasks that require careful planning or mathematical reasoning, dialling the effort level up earns back its cost in correctness. Layer 2: The Orchestration Framework If the foundation model is the brain, the orchestration framework is the nervous system. It handles the control flow: deciding what the agent should do next, when it should call a tool, how it should handle the result, and how the whole reasoning loop stays coherent across multiple steps. The pattern that most frameworks implement is called ReAct (Reasoning and Acting). The agent produces a thought, decides on an action, executes the action through a tool, observes the result, and then thinks again. This loop repeats until the agent produces a final answer. It sounds simple. In practice, it is where most production failures occur: the agent calls the wrong tool, gets stuck in a loop, or fails to recognise when it has enough information to stop. LangChain is the most widely adopted framework. It offers a large ecosystem of integrations and good documentation. The criticism that it adds too much abstraction is fair at the prototype stage, but less relevant once you need the features that abstraction provides. LangGraph, built by the same team, is better suited for stateful multi-agent workflows where you need fine-grained control over the execution graph. If your agent involves multiple specialists coordinating on a task, LangGraph is the cleaner choice. CrewAI is designed specifically for multi-agent coordination. It lets you define agents with roles, assign them tasks, and have them collaborate within a structured workflow. It is higher-level than LangGraph and faster to get running, but gives you less control over the execution details. AutoGen, from Microsoft, takes a conversational approach to multi-agent systems. Agents interact with each other through a message-passing interface, which makes the interaction logic very readable. Semantic Kernel is Microsoft’s enterprise-focused option, with production-ready support for C#, Python, and Java. If you are operating in an enterprise environment already running on the Microsoft stack, it fits naturally. LlamaIndex started as a document ingestion and retrieval framework and has since grown into a full agent framework, with particularly strong support for RAG-heavy workflows. The right choice depends on what your agent needs to do. For a single-agent task runner: LangGraph or LangChain. For a coordinated team of specialized agents: CrewAI or AutoGen.
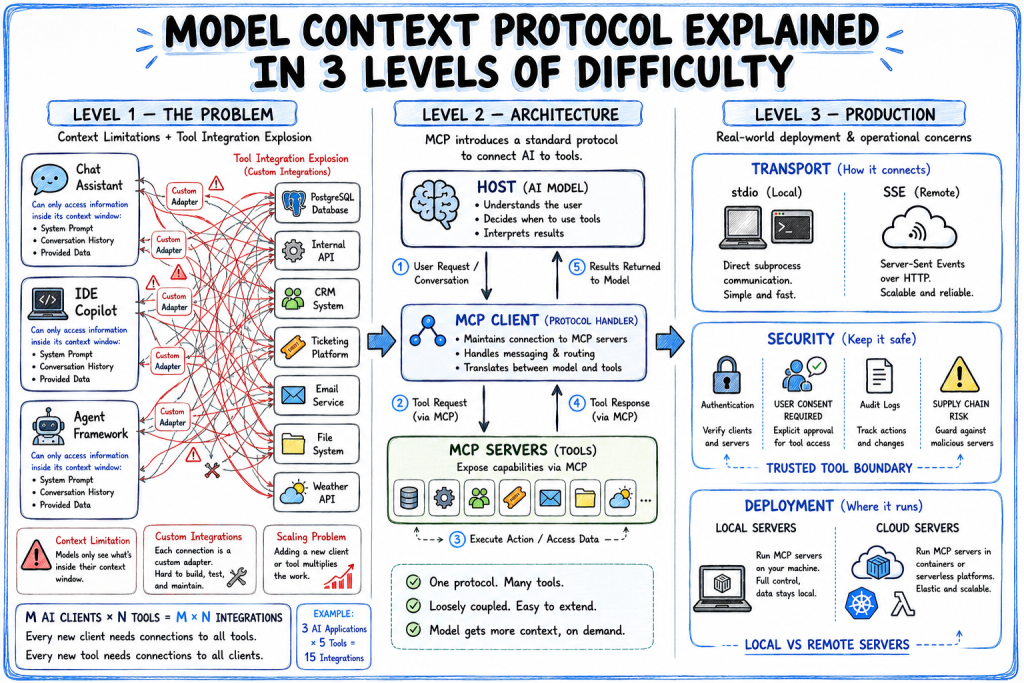
Model Context Protocol Explained in 3 Levels of Difficulty
In this article, you will learn how the Model Context Protocol (MCP) standardizes the way AI applications connect to external tools and data sources, broken down across three levels of depth. Topics we will cover include: Why connecting models to external systems without a shared standard creates an integration problem that grows with every new client or tool. How the host, client, and server work together, and what happens when a model’s request flows through an MCP server. The transport options, security risks, and deployment choices that matter once an MCP server is running in production. Introduction Every large language model has the same limitation baked in: its knowledge stops at training time. Ask it about a file on your machine, a row in your database, or an email that came in this morning, and it either halts or guesses. The model is sealed off from the systems your application actually runs on, and bridging that gap falls entirely on the developer. The usual approach is to write custom integrations — a function here, a tool definition there — that pipe external data into the context window. That works at a small scale. But once you’re connecting multiple models to multiple services, you end up maintaining a matrix of one-off adapters, each with its own auth logic, schema assumptions, and failure modes. Adding a new model or a new service means reworking that whole matrix again. The MCP is an open standard, introduced by Anthropic, that gives this problem a cleaner shape. Instead of every AI application building its own connectors to every external system, both sides implement a shared protocol. A service exposes itself as an MCP server once, and any MCP-compatible client can use it. This article walks through how MCP works at three levels: why the problem exists and what MCP’s core idea is, how the architecture fits together and what a request looks like, and finally the transport, security, and deployment decisions that matter when you take it to production. Level 1: Why MCP Matters A model can only work with information available in its context window: the system prompt, conversation history, and any additional data provided during the interaction. Accessing information outside that context requires external tools. Most AI systems support tool calling. When a model requests a tool, the application executes the request, retrieves the required data, and returns the result to the model. This allows models to interact with databases, APIs, file systems, and other external systems. As the number of AI applications and external tools grows, integration complexity increases. Consider: M AI clients (chat applications, IDE assistants, agent frameworks, model providers) N tools and data sources (databases, APIs, internal services, SaaS platforms) Without a shared standard, each client typically requires its own integration with each tool. The number of client-tool adapters can therefore grow as M × N. For example, if three AI applications need access to five internal tools, you may end up building and maintaining fifteen separate integrations. Adding a new tool requires integrating it with every client. Adding a new client requires integrating it with every tool. The Problem That MCP Solves MCP provides a standard way for AI applications and external systems to communicate. AI applications implement the MCP client specification. Tools and data sources expose capabilities through MCP servers. Because both sides follow the same protocol, an MCP server can be used by any compatible MCP client without requiring a custom integration for that specific client. Instead of building a separate adapter for every client-tool pair, each client implements the MCP protocol once and each tool implements it once. The integration surface shifts from approximately M × N custom adapters to M + N protocol implementations. The practical result is a more composable ecosystem. An MCP server that exposes a PostgreSQL database, internal API, or ticketing system can be used by multiple assistants, IDEs, and agent frameworks through the same protocol rather than through separate integrations for each platform. Level 2: MCP Architecture and How a Request Flows MCP interactions involve three parts: the host, the client, and the server. The Host The host is the application the user actually talks to. This can be a chat interface, an AI-powered IDE, or a custom agent. It contains the language model and drives the conversation. When the model decides it needs to reach out to an external system, that decision originates here. The Client The client sits inside the host and handles protocol mechanics. It maintains a registry of available MCP servers, translates the model’s requests into properly formatted MCP calls, dispatches them to the right server, and converts responses back into something the model can use. From the model’s perspective, it just asks for things. The client handles the plumbing. The Server The server is your bridge to an external system. It registers its capabilities — what tools it offers, what data it can provide — and responds to requests from clients. A server sitting in front of a database takes a structured tool call from the client, runs the appropriate query securely, and returns results in a format the model can work with. The server owns all the implementation details of that system; the client and model only see the MCP interface. MCP Host, Clients, and Server Tracing a Request Say a user tells an AI assistant: “Grab the Q2 revenue numbers from the database and put together a summary for the team.” The model sees it needs two things it can’t do on its own. The client checks its registered servers and finds a database_query tool and an email_draft tool on two separate MCP servers. The model calls database_query with the relevant parameters. The server runs the query, formats the results, and sends them back through the client to the model. Now working with real numbers, the model calls email_draft — recipient list, content, subject. The email server handles the rest, confirms success, and the model tells the user it’s done. Neither server knew
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/grok-4-5-enters-private-testing-at-spacex-tesla-elon-musk-3058228.html” on this server. Reference #18.c4f43717.1782664837.99dac3d https://errors.edgesuite.net/18.c4f43717.1782664837.99dac3d
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/google-restricts-meta-s-access-to-gemini-ai-capacity-amid-computing-constraints-3058233.html” on this server. Reference #18.eff43717.1782660930.7b38ce7 https://errors.edgesuite.net/18.eff43717.1782660930.7b38ce7
Access Denied
Access Denied You don’t have permission to access “http://zeenews.india.com/technology/apple-raises-macbook-ipad-prices-in-india-by-up-to-rs-70000-check-new-prices-of-macs-apple-tv-and-homepod-3057783.html” on this server. Reference #18.eff43717.1782461033.279538ce https://errors.edgesuite.net/18.eff43717.1782461033.279538ce

